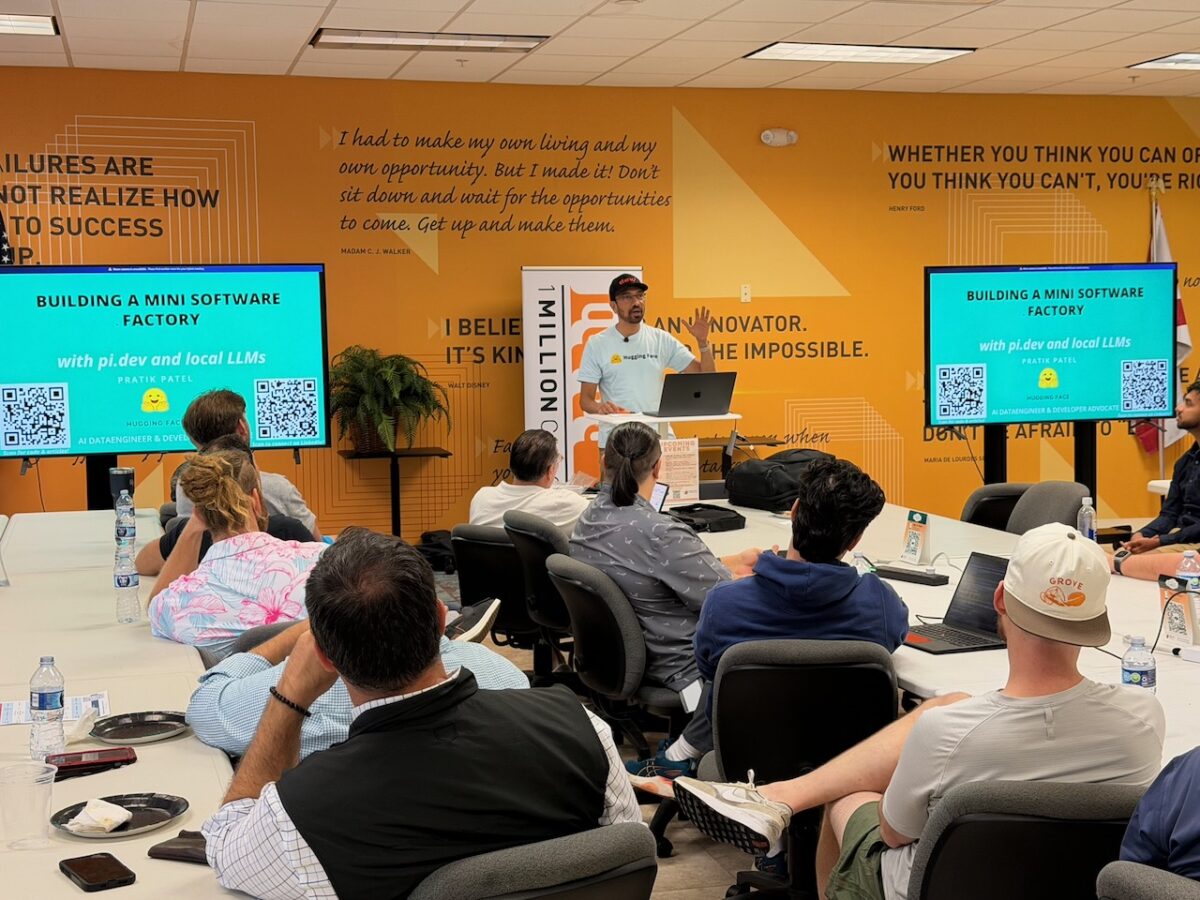
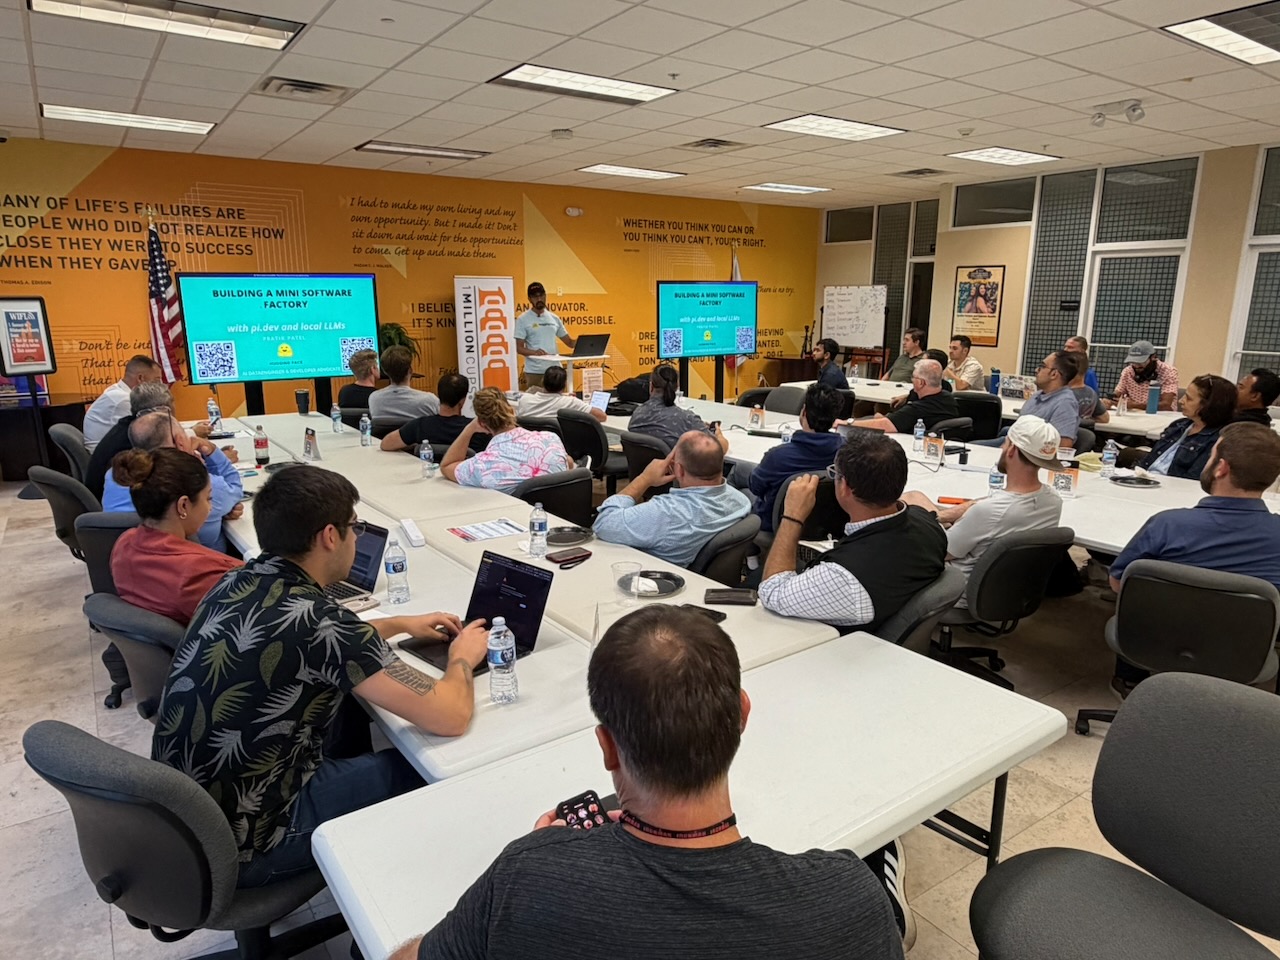
On Monday, September 14, Pratik Patel gave his talk, Building a Mini-Software Factory using Pi.dev and Local LLMs, to a full room at the Entrepreneur Collaborative Center in Tampa’s Ybor City neighborhood. Here are my notes from his talk.
Blasphemy!
The quite-full ECC was about three-quarters software developers, and Pratik had just finished taking a headcount of the Java people, the TypeScripters, the Pythonistas, and of course, the Rustaceans (“most people want to rewrite everything in Rust, and I find it extremely annoying”). That’s when he said what would’ve gotten him tarred, feathered, and run out of a Java meetup if we’d been back in the days of Java SE 18 or 19:
“One of the things that you may get from this session is that the programming language doesn’t even really matter anymore.”
Of course, his paln was to prove that statement by the end of the night, as well as the conclusion that you should draw if you still plan to remain in software: If you hand the coding off to a machine, the valuable work moves up the stack.
Pratik is a longtime Java/JVM guy, one of the organizers behind the DevNexus conference in Atlanta, and as of about a month ago, he works at Hugging Face. He also polled the room on what Hugging Face actually does, and enjoyed the answers (mine: “Hang out with Jensen!”). The correct one, which he eventually told us, was that they own Transformers and the rest of the library stack that lets you download, and better still run the models.
The gamble: Building before the presentation
It takes time for an software factory to build things, even on a late-model MacBook with 64GB RAM like Pratik’s. Sp he started the demo at the beginning and then talked over it, which I suppose is the new version of “live coding”. I do that myself (both live agentic coding as well as raw-dogging the code the old-fashioned way), so I have to respect Pratik’s boldness.
He asked the room for an app idea. Someone suggested a horse-boarding scheduler, which was too big. Charles, who works for a sports organization, suggested a playoff odds calculator. Pratik assessed that it was doable within the given time, so he agreed to build that.
Pratik opened Gemini and, off the cuff, dictated a rough spec: look at the remaining season schedule for all 30 MLB teams, calculate each team’s chance of making the playoffs, and let the user tweak the metrics on the page to try different scenarios.
Gemini spat out a 255-line spec in a few seconds. He pasted that into his software factory, told it “Create a new app called MLB Odds, here’s the spec, let me know when it’s finished and what the URL will be,” hit enter, and walked away from it to start the actual presentation.
“Again,” he said, “this may be a total disaster. It may not work, but let’s see how it goes.”
So what is a software factory?
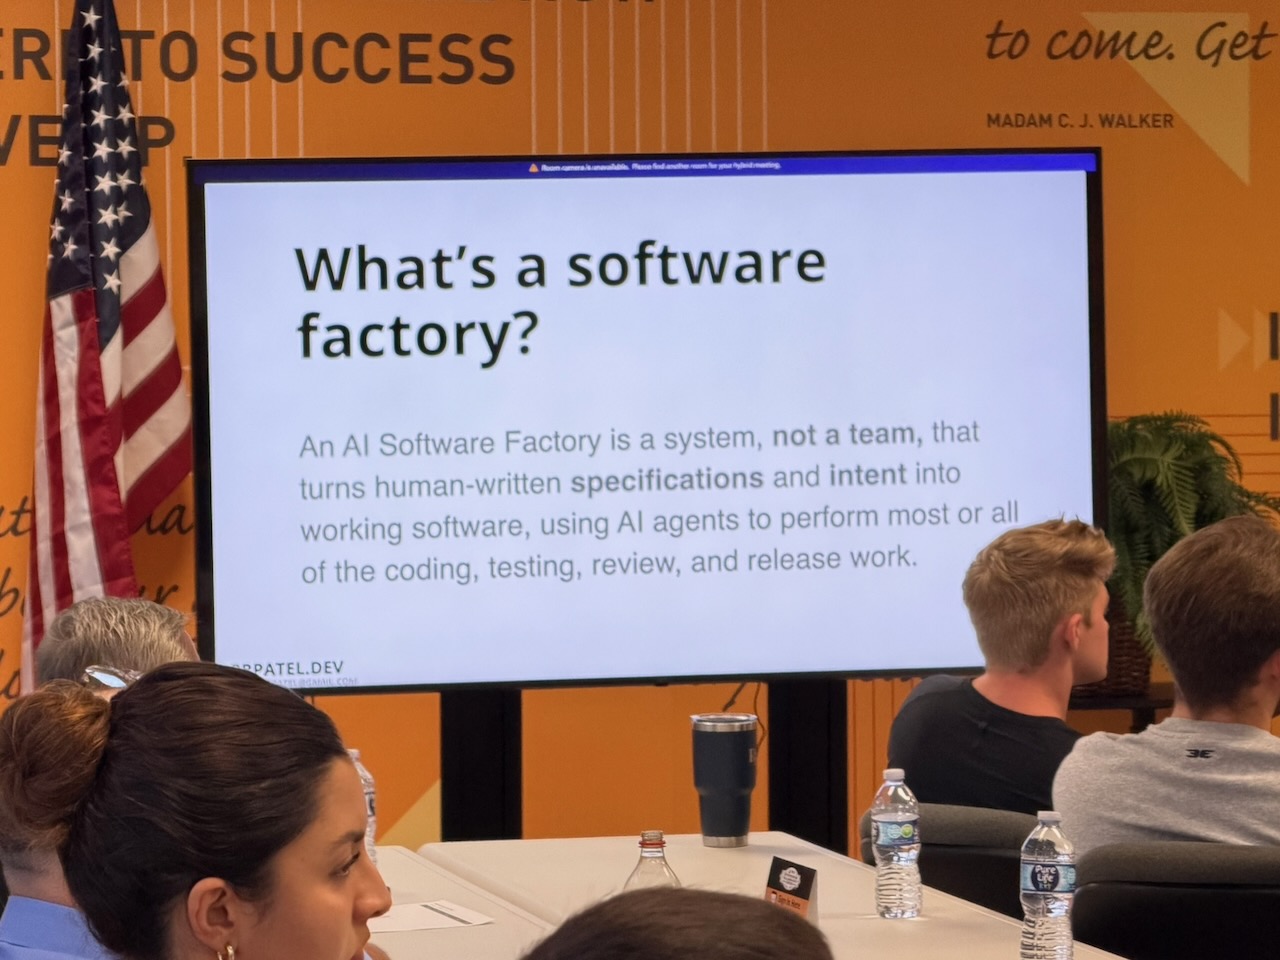
Pratik was upfront that this is the most undefined term in the industry right now: “If you ask 10 people in this room what a software factory is, you’ll probably get 10 different answers.” Here’s his:
An AI software factory is a system, not a team, that turns human-written specifications and intent into working software, using agents to perform most or all of the coding, testing, review, and release work.
The key word is system. You say “go build this,” walk away, and come back hours or a day later to working software. It’s like handing a project to a team of engineers and going off to do something else (or hey, nothing. You’re the boss!).
And critically, a software factory is not one-shotting. Telling Claude or ChatGPT “build me this website” and pasting in a detailed description relies entirely on the raw intelligence of the model. A factory applies rigorous software engineering process around the model: planning, architecture, implementation, testing, QA, security review, version control. The process is the product.
The levels: where you are on the ladder
Pratik walked through a progression that got a lot of nodding in the room:
- L0: Manual coding: Open an editor, translate what’s in your brain (or in a written spec) into code, hit a wall, go read the docs or Stack Overflow, keep going.
- L1: “Spicy autocomplete”: IDEs got language servers and started completing large fragments for you. A genuine step change in velocity.
- L2: AI pair programmer: You describe what you want to a chatbot, it emits code, you copy it into your editor and fix it up. You’ve effectively stopped going to Stack Overflow directly, because the model already ate it.
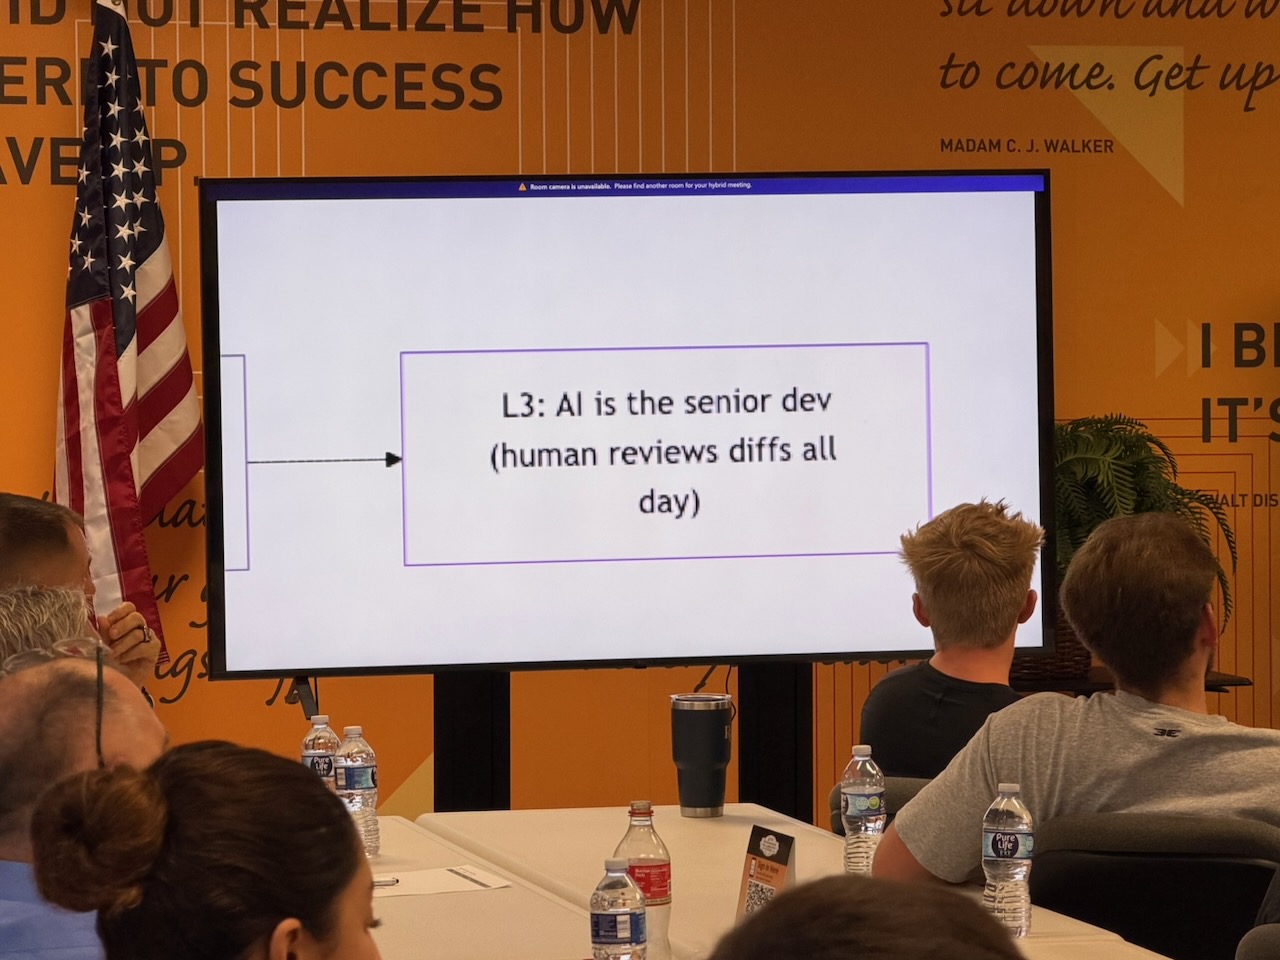
- L3: AI as a senior developer: You give it a spec, it builds, you review the code and tell it when it picked the wrong approach.
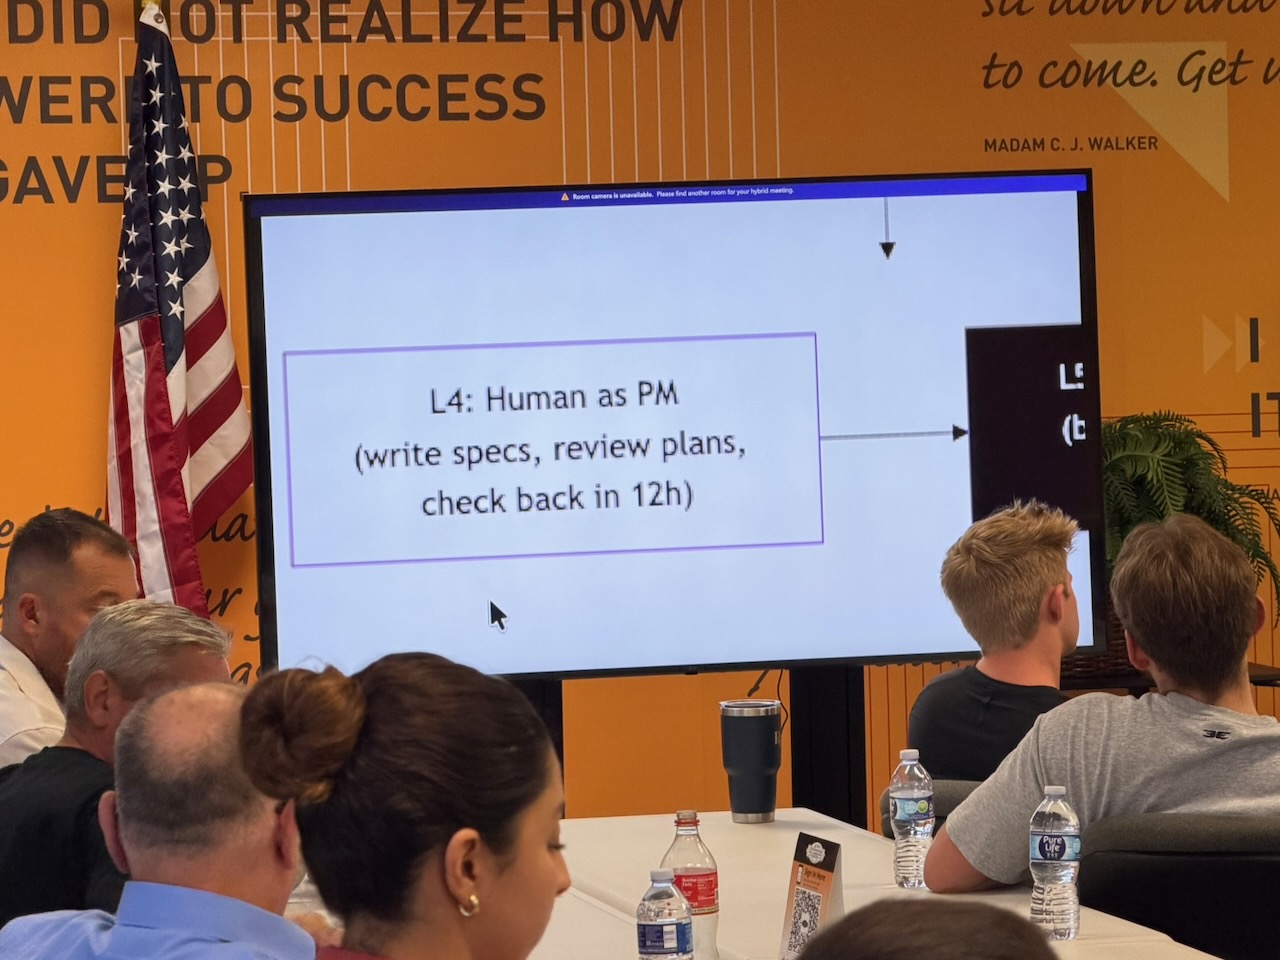
- L4: You’re the PM: You write specs, you review plans, you check back later.
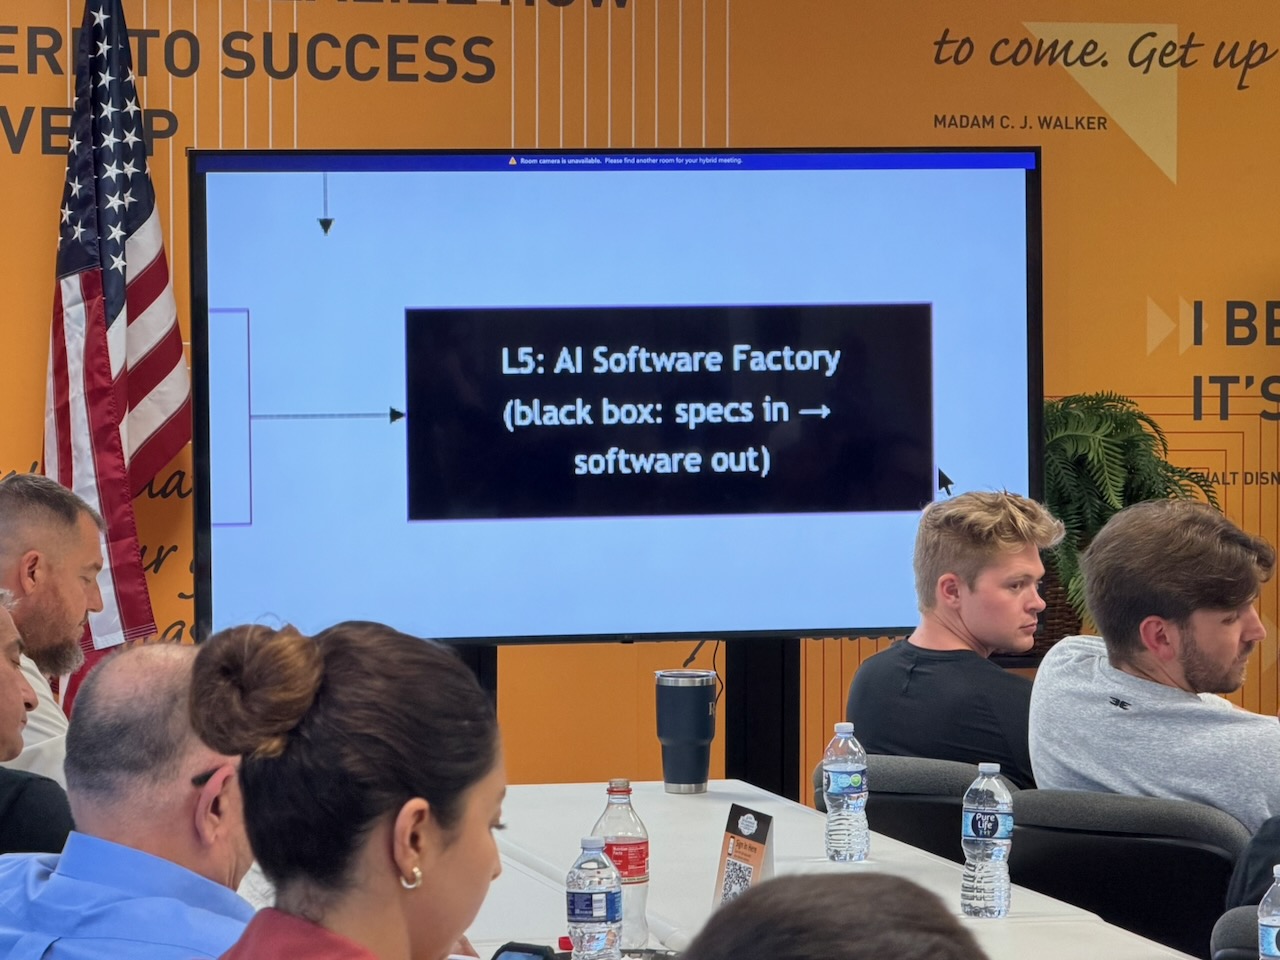
- L5: Software factory: specs go in, software comes out. You review the product, and you may never look at the code at all.
His take: most working developers are somewhere between L2 and L4 right now, depending on how much freedom their employer gives them.
What’s left for software engineers, then?
Pratik clearly flagged this part as his own opinion. Like a lot of developers, myself included, he went through the “there’s no way AI replaces me” phase. He concluded that it doesn’t replace software engineers, but it does dramatically change what they spend their day doing, which is the remaining high-value work. I get the feeling that programmers went through something similar when going from assembly to higher-level languages.
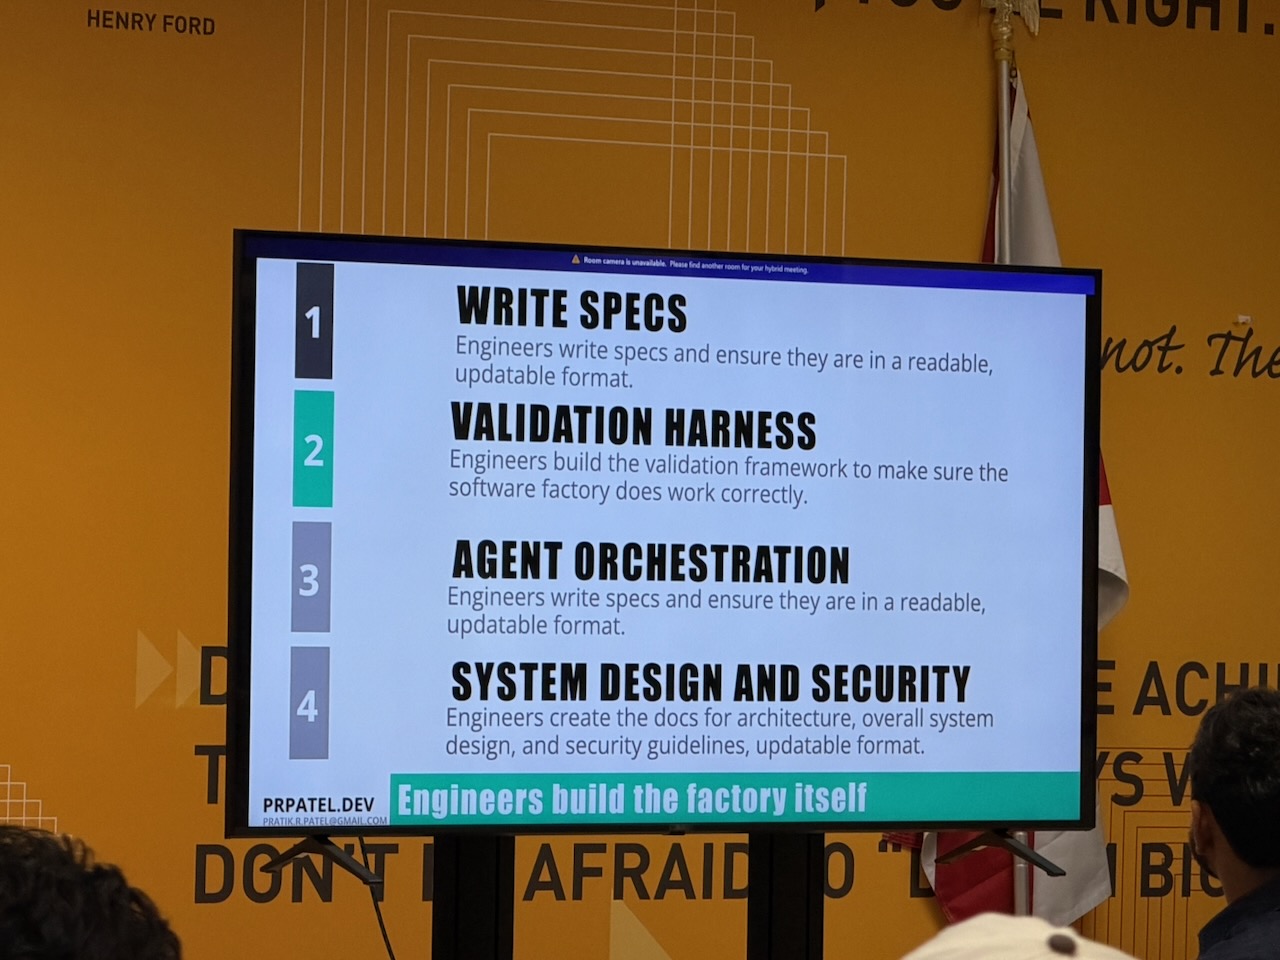
With AI writing the code, the process of programming becomes even higher-level, with these becoming our main activities:
- System design. The model knows how to write code. It does not know that you can’t build a browser front end in Python, and it doesn’t know that your real-time app needs in-memory caching to hit a sub-three-second response. And if it improvises those decisions unprompted, you will not like the implementation.
- Security.
- Making sure user requirements are actually met.
- Writing and maintaining the specs and the architecture.
- Building the validation harness that keeps the factory honest.
- Agent orchestration.
He also noted, to the product managers in the room, that the line between PM and engineer is blurring fast in both directions.
The four jobs of a factory
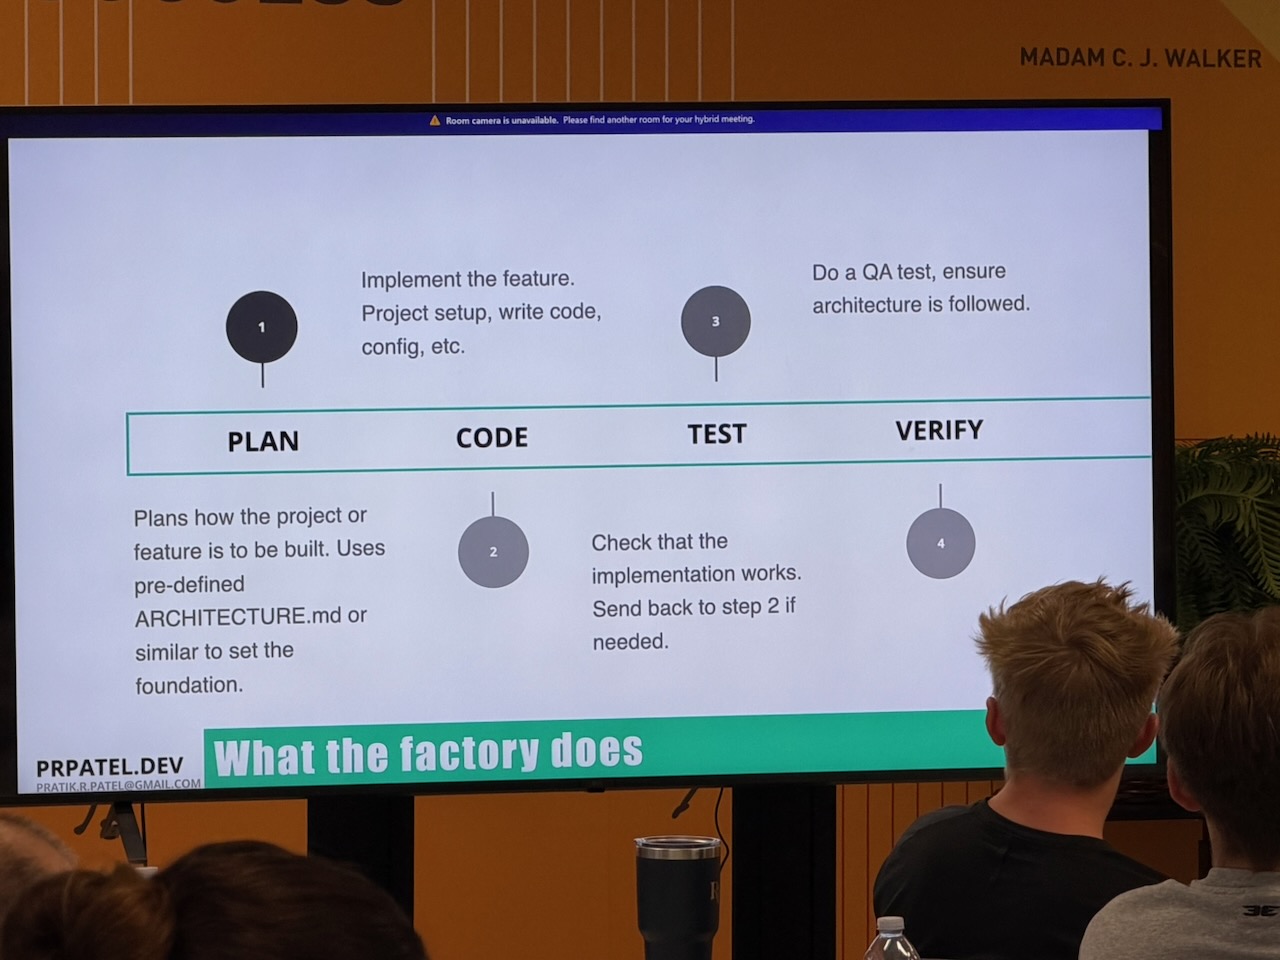
At minimum, Pratik argues, a software factory has to do four things:
- Plan the build
- Code it
- Test it (looping back to implementation when tests fail)
- Verify with a QA/security/architecture-compliance pass (the kind of review a human QA engineer would do by using the result as a user would, not just unit tests)
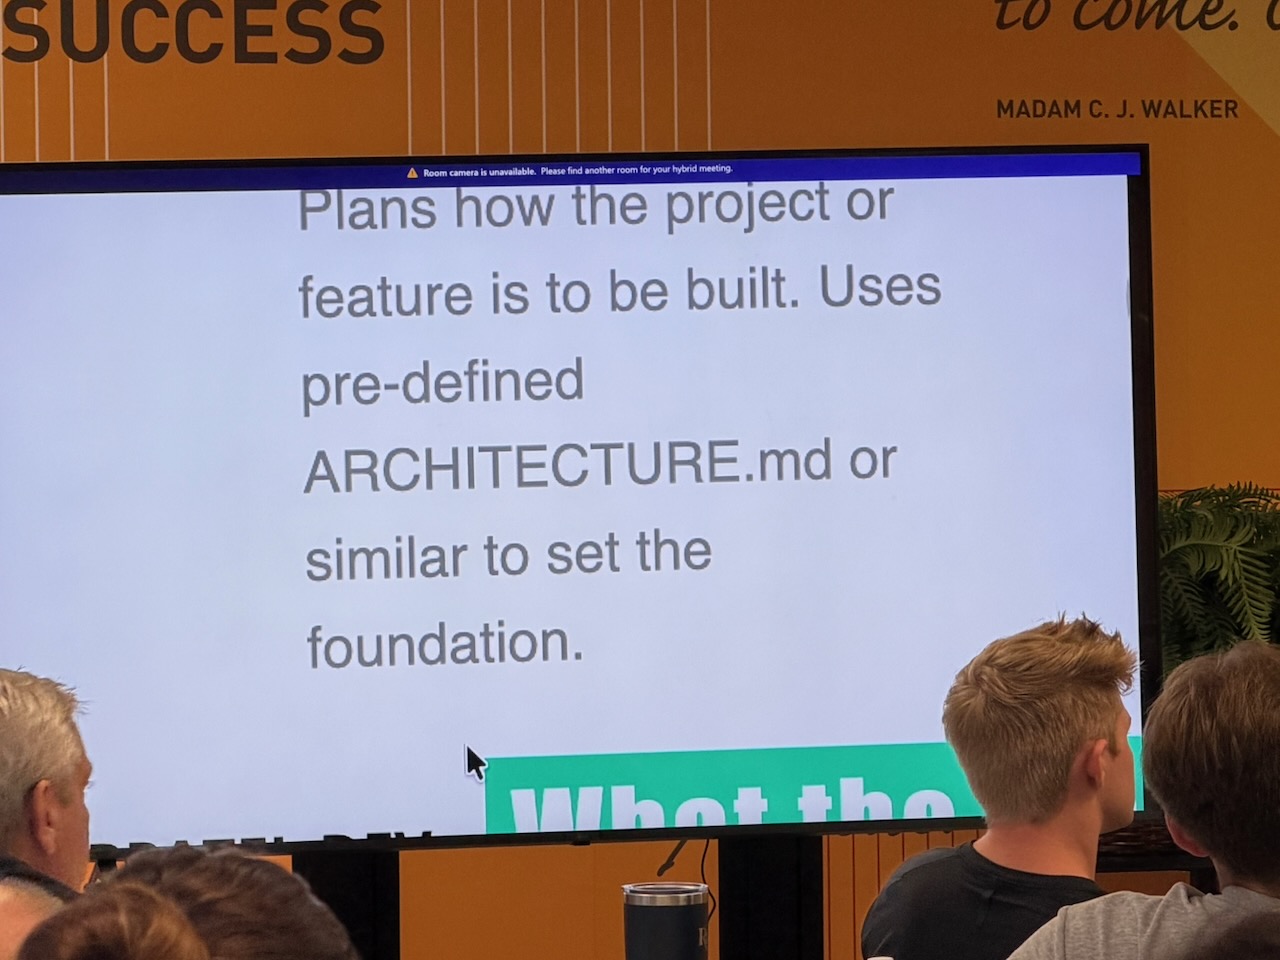
The single most important artifact in all of this is architecture.md. That file is where you, the engineer, do the system design: “This is a web app, use Vue, this is the backend, these are the performance targets, this is how we build things around here.” It’s exactly what you’d tell a new team lead. The factory can’t extrapolate it from your brain.
Specs are a separate thing from architecture: specs are the features, architecture is the system. For spec format, Pratik mostly just writes Markdown, though he noted that larger teams use a more rigid PRD structure, and GitHub’s Spec Kit is out there if you want something opinionated.
Pratik’s actual stack
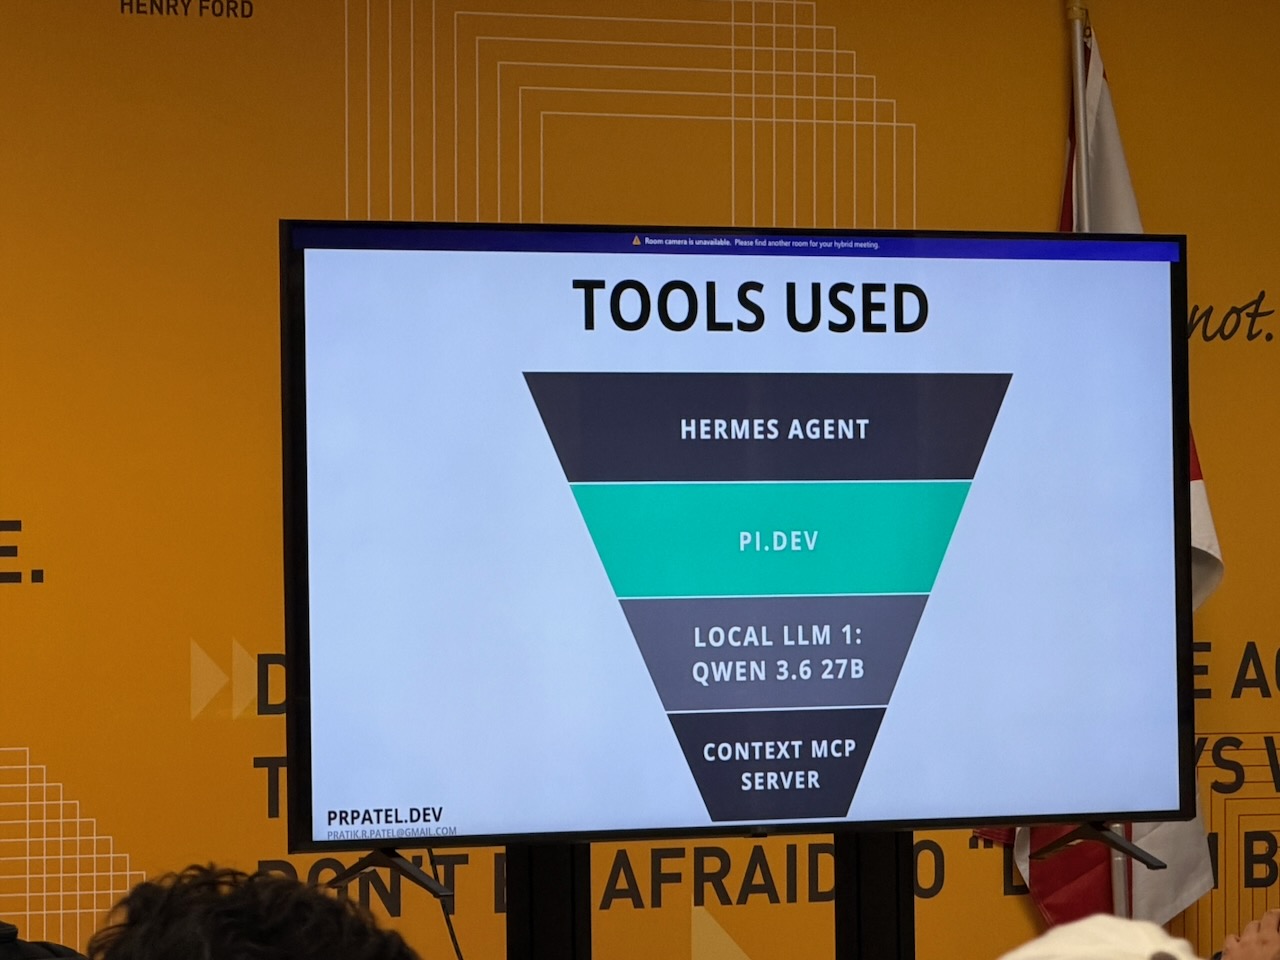
Here’s what he’s running, top to bottom:
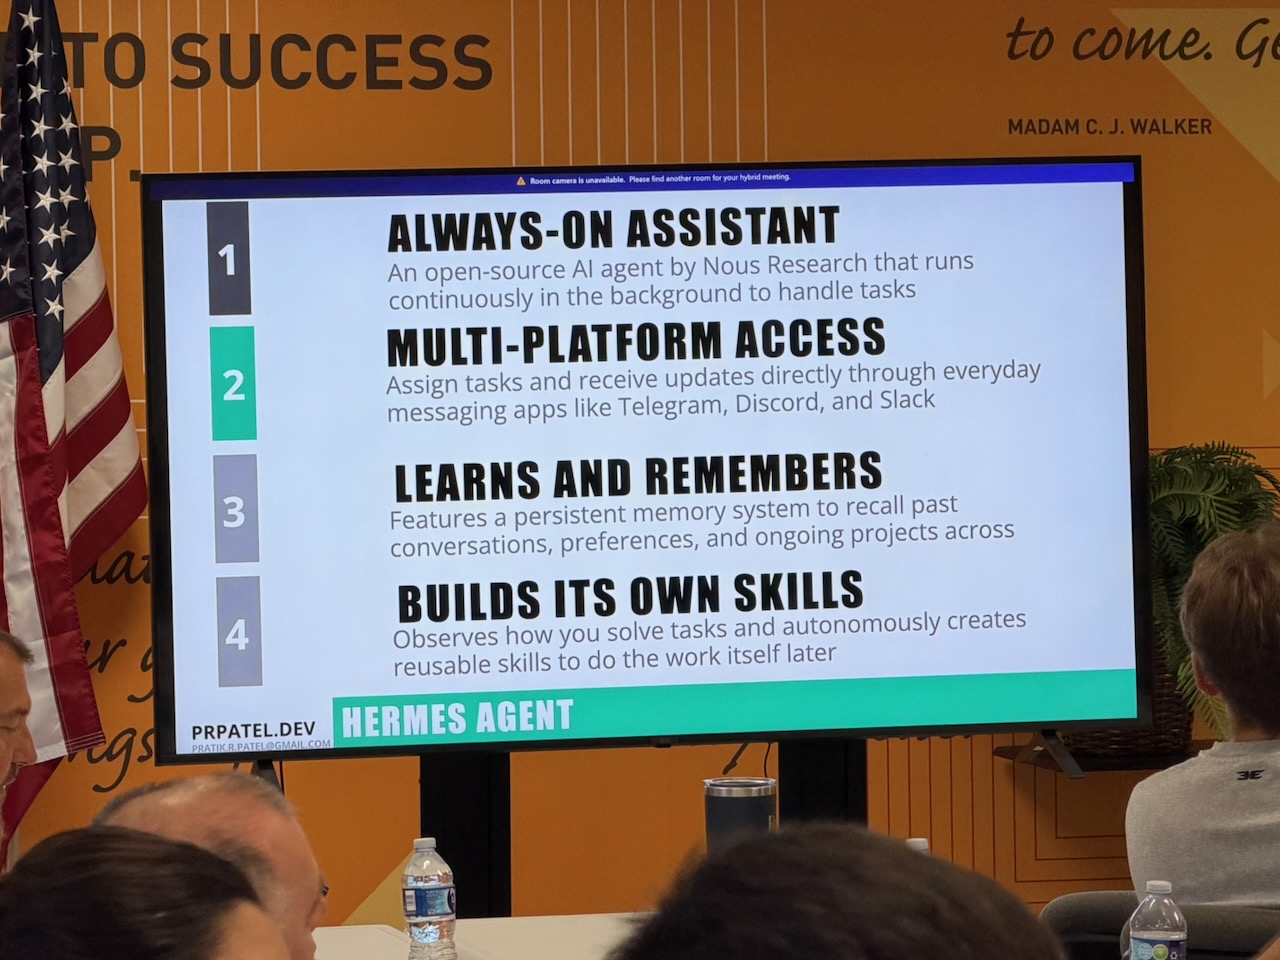
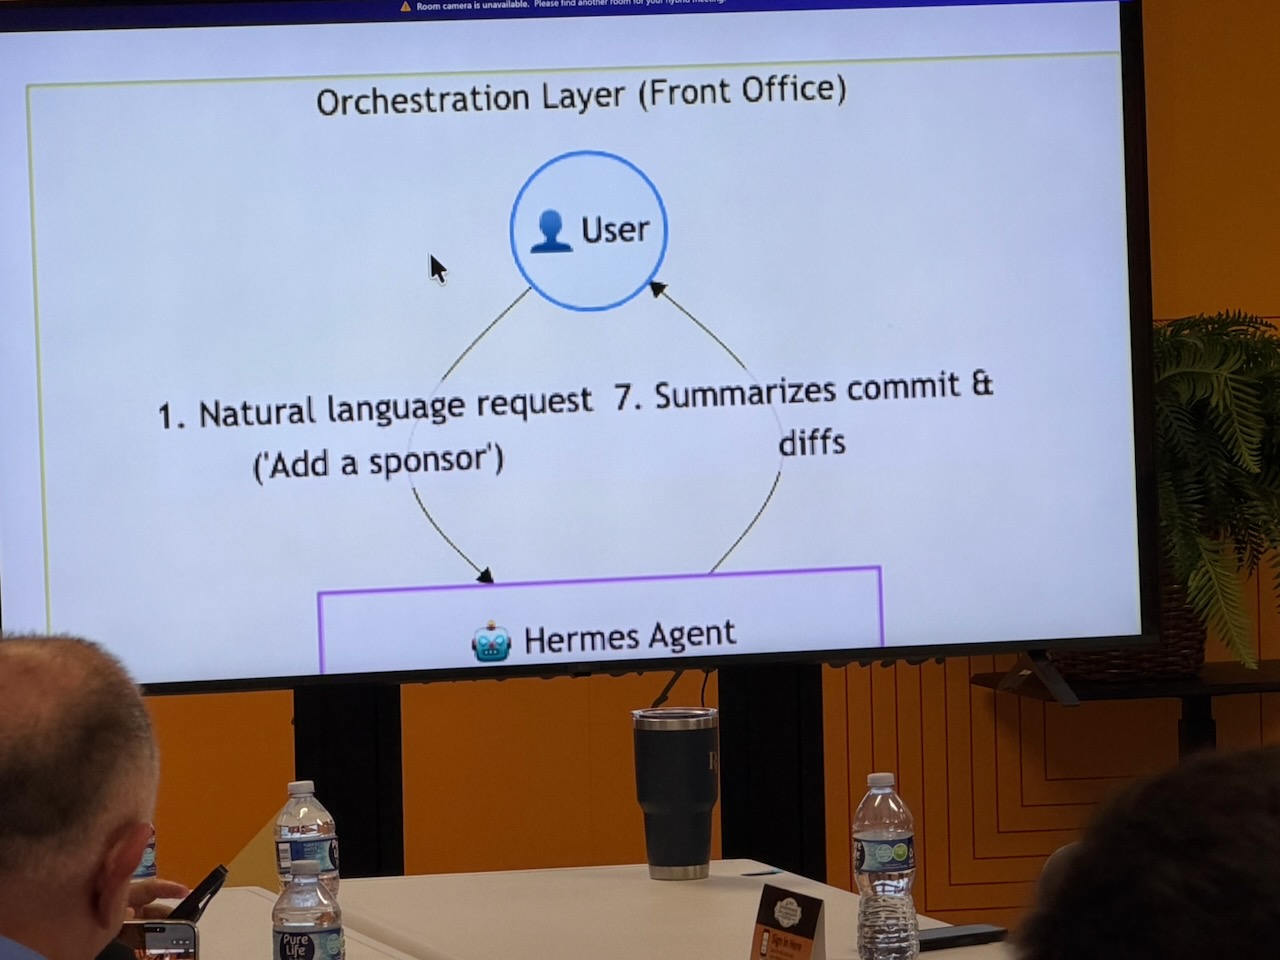
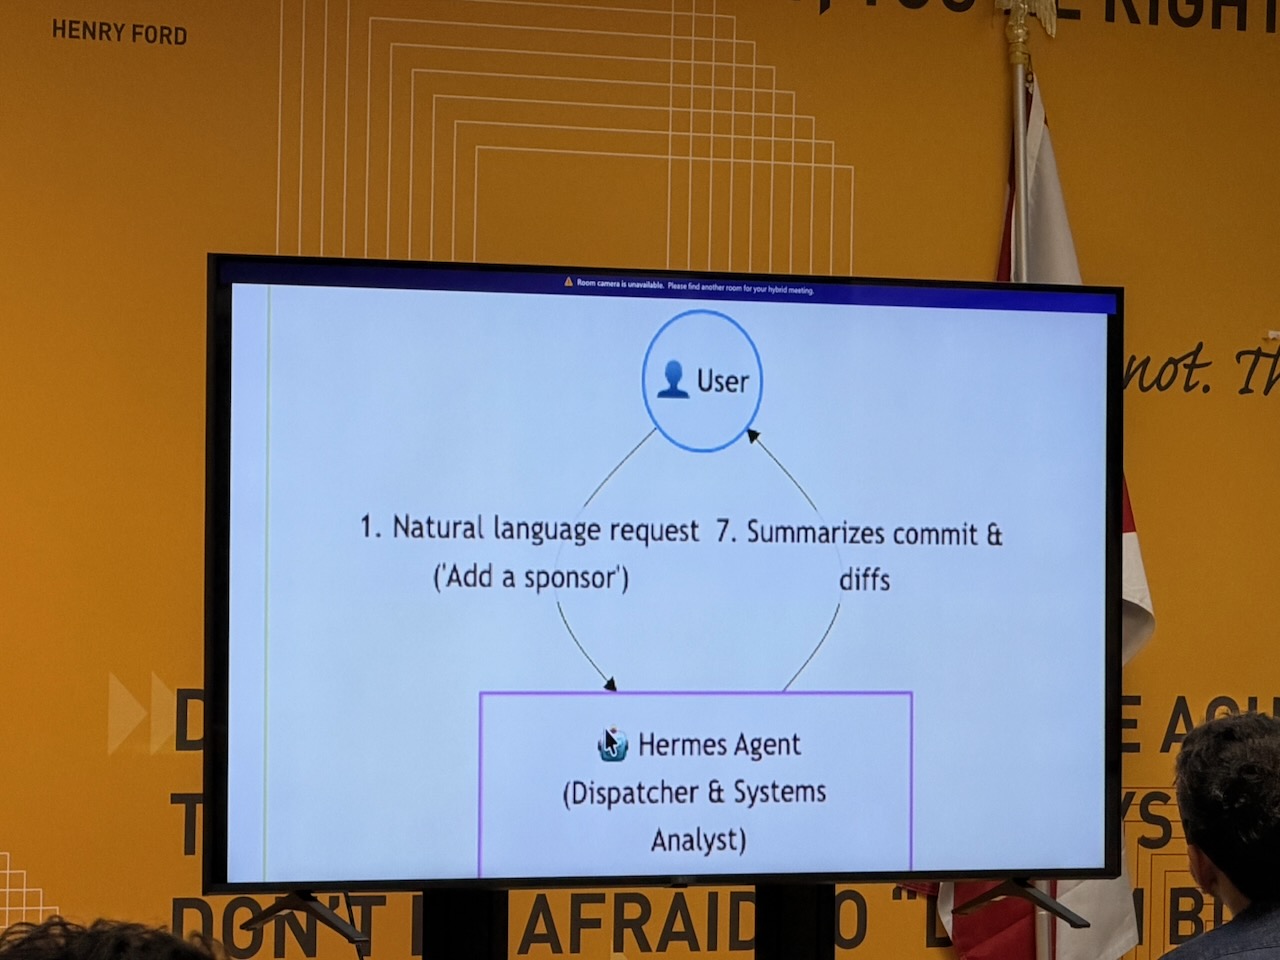
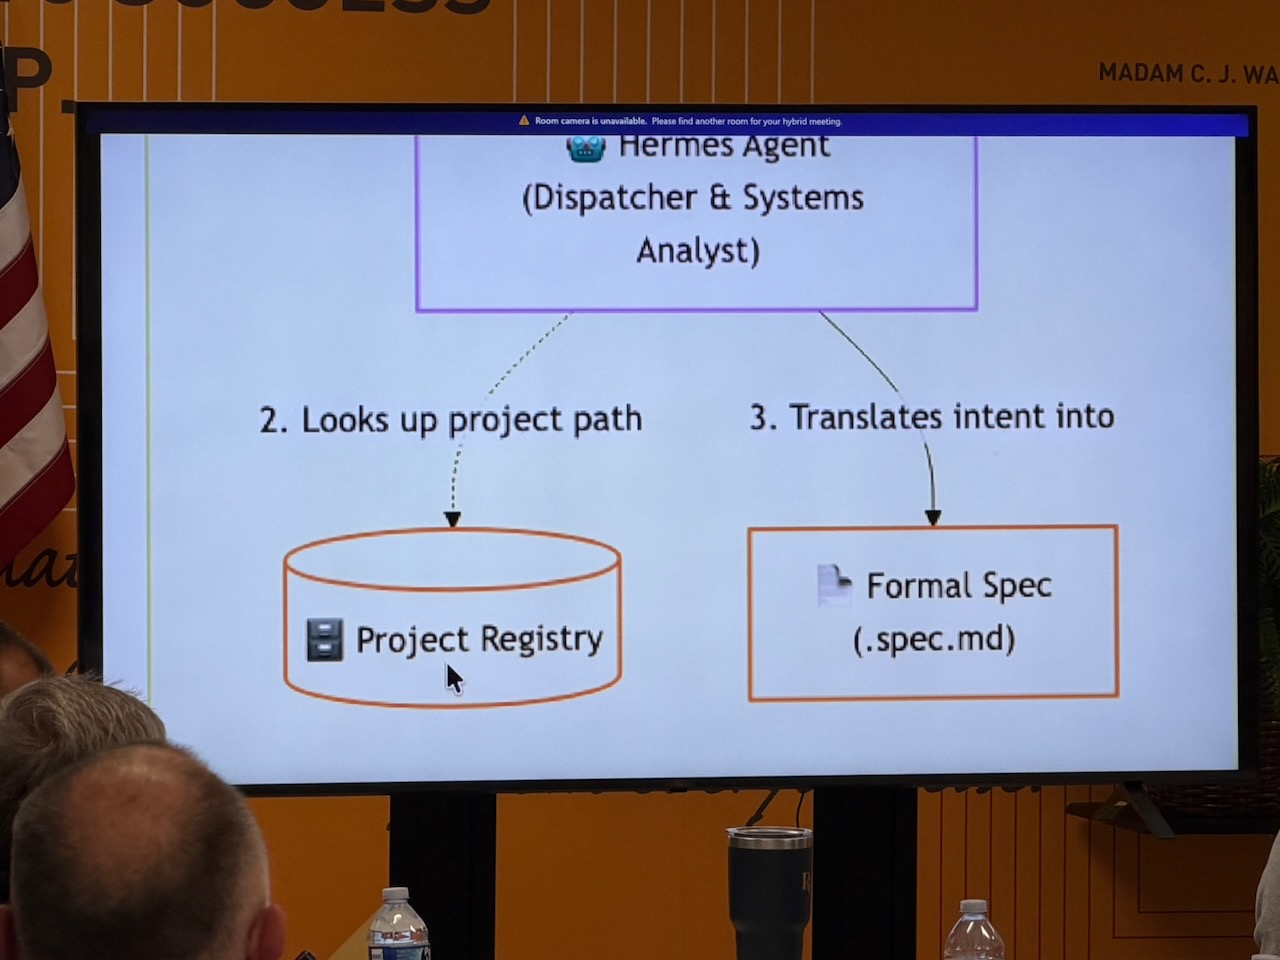
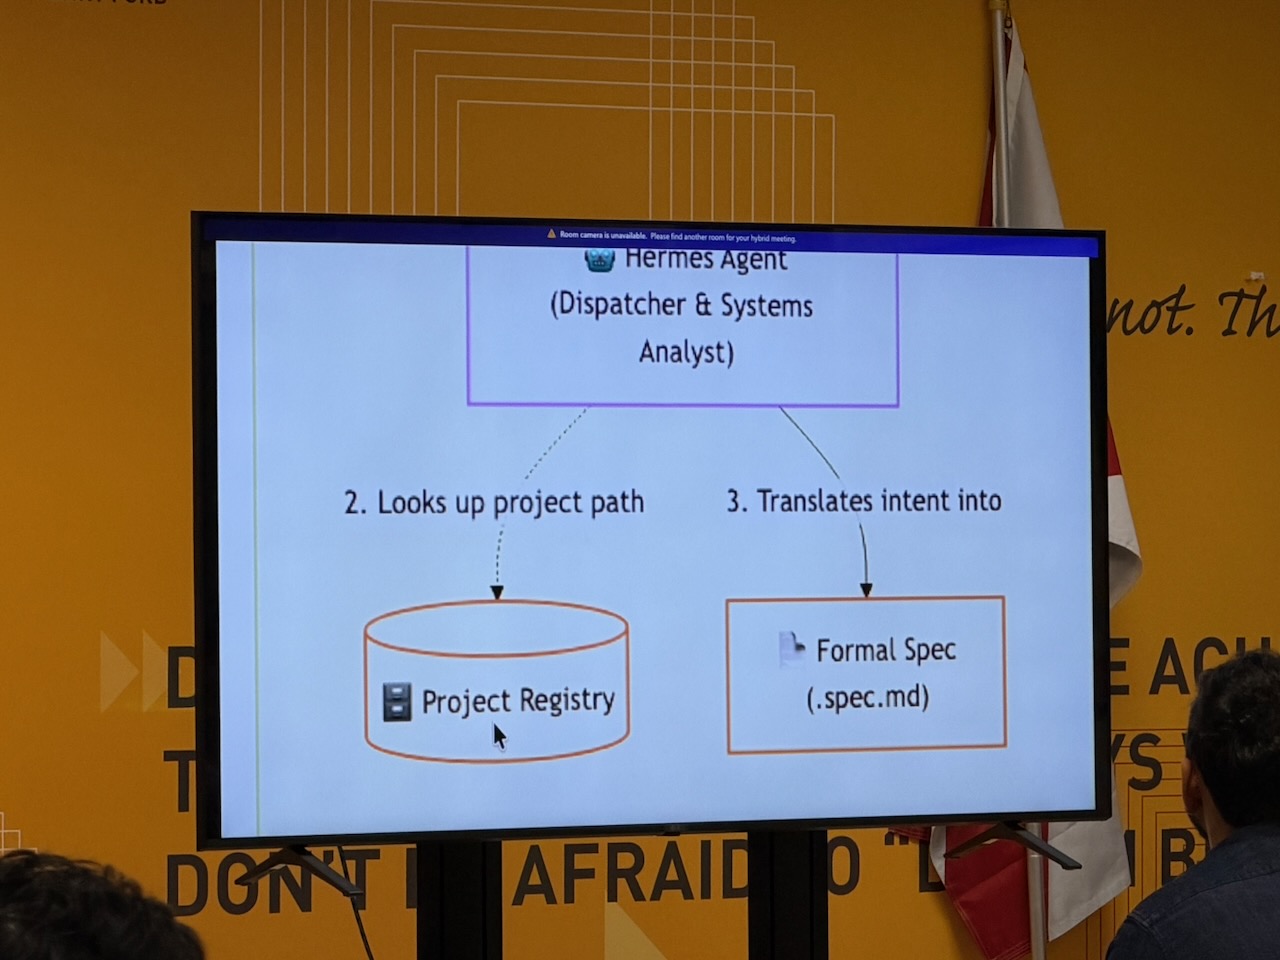
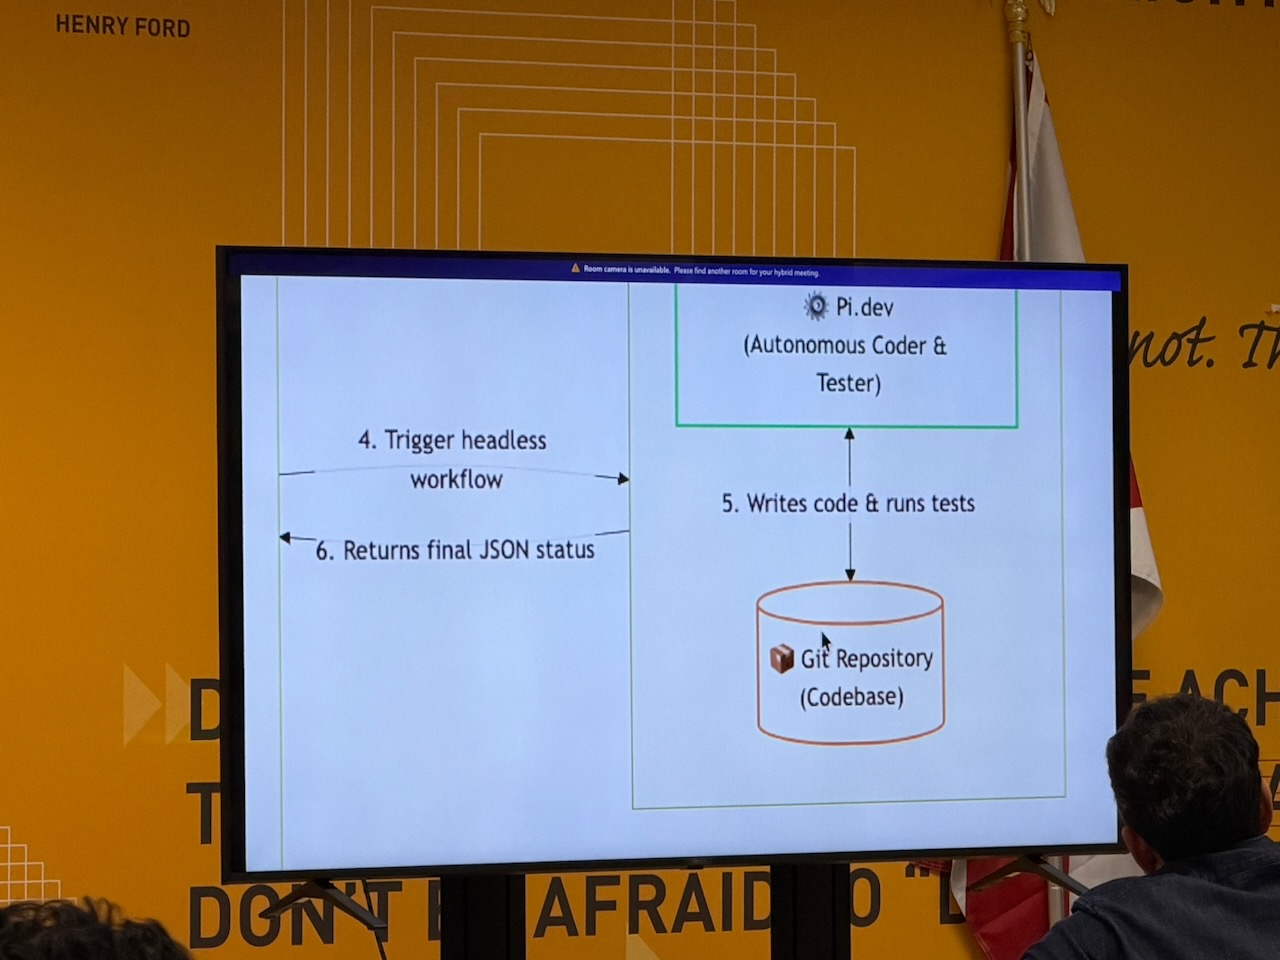
Hermes Agent as the front office. Hermes (the open-source, self-hosted personal agent from Nous Research, in the same category as OpenClaw) is his always-on orchestrator. It runs on a server, it’s reachable via Telegram, Discord, Slack, or email, and it has persistent memory that turns repeated requests into reusable skills. Hermes takes his request, polishes it into a formal spec, finds the right project directory, and dispatches a headless job to the factory floor. He runs it on a 35B-A3B Qwen model, which has 35 billion parameters, but only 3 billion active per token, so it fits on a modest server.
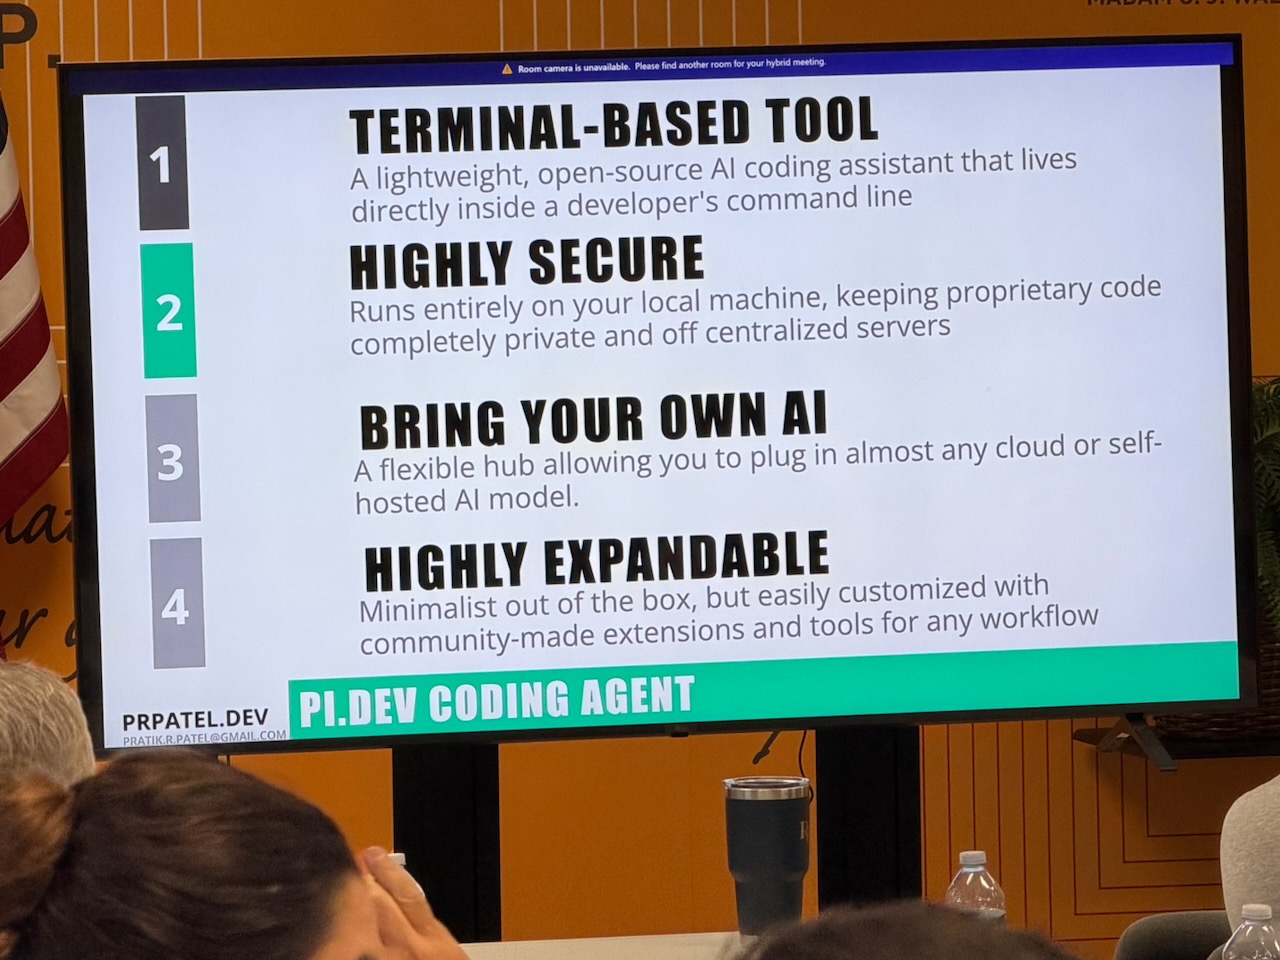
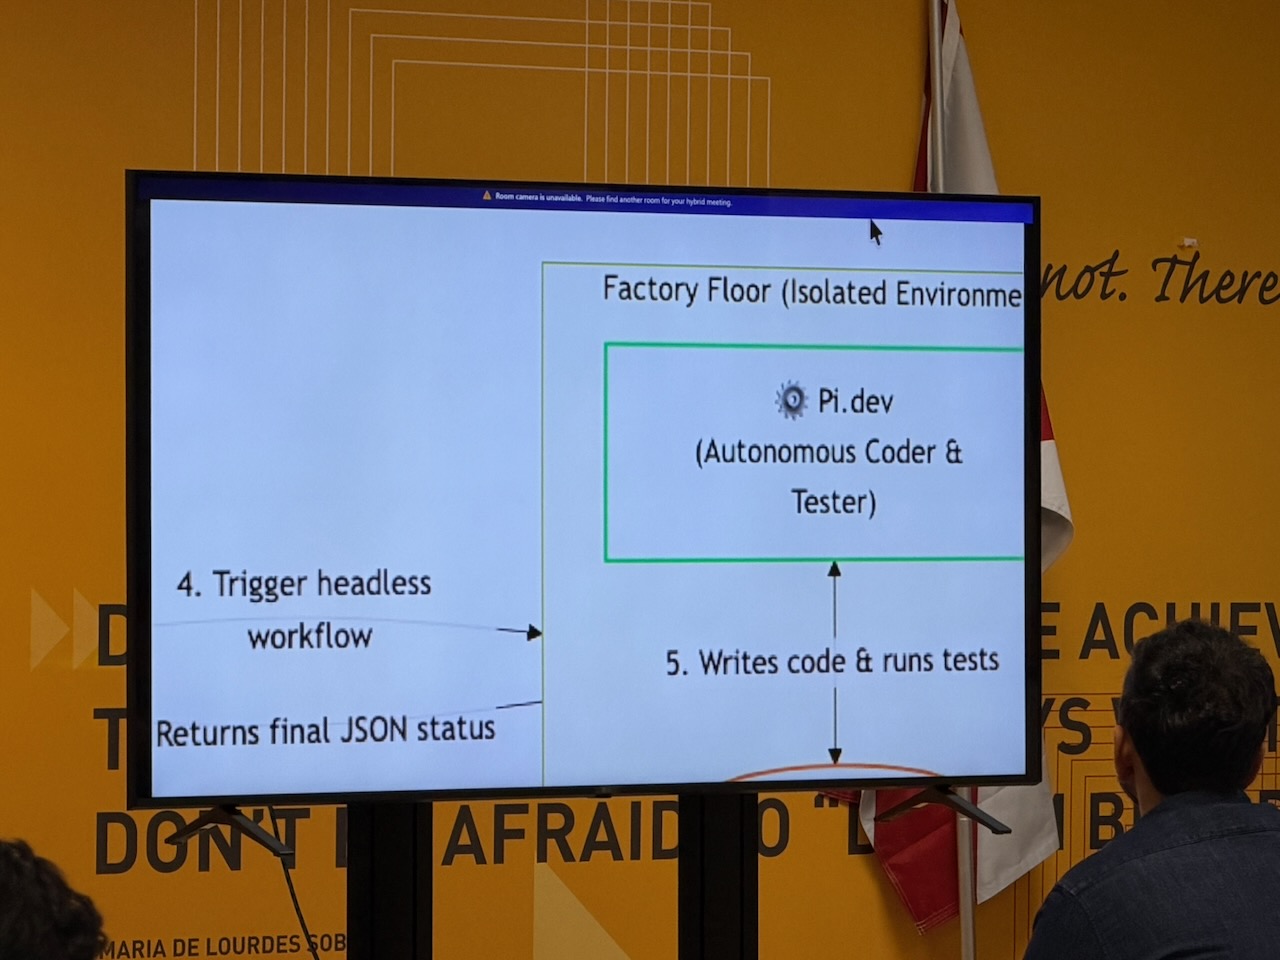
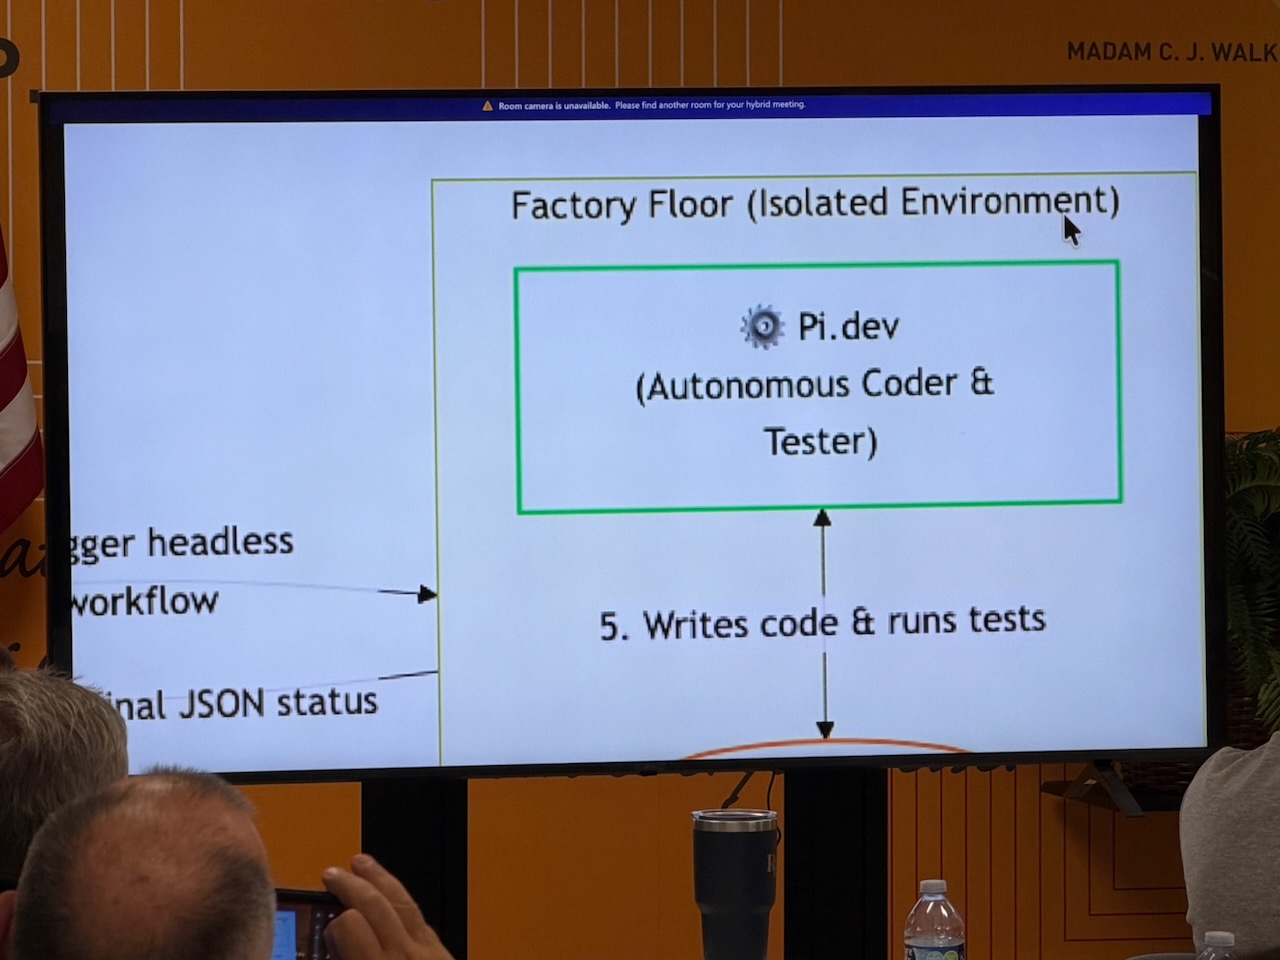
pi.dev as the factory floor. pi.dev is Mario Zechner’s minimal terminal coding harness. It ships with four tools: read, write, edit, bash. It has a tiny system prompt, and hooks for everything else. That’s it: it’s a build-your-own coding agent, not a sealed product. Pratik picked it over Claude Code, Codex, Cursor, OpenCode, Kiro, and the rest because it’s lightweight, it doesn’t burn tokens, and you can point it at any model you want.
Someone reasonably asked why he didn’t just use Hermes for the coding too, since Hermes can code. His answer was about context hygiene: he wants Hermes to be the manager and pi to be the worker, and he doesn’t want to pollute the coding agent’s context with all the management and channel-routing overhead. “It doesn’t have memory. It doesn’t have learning. I don’t want all that stuff for my worker software monkey that’s going and building the code.”
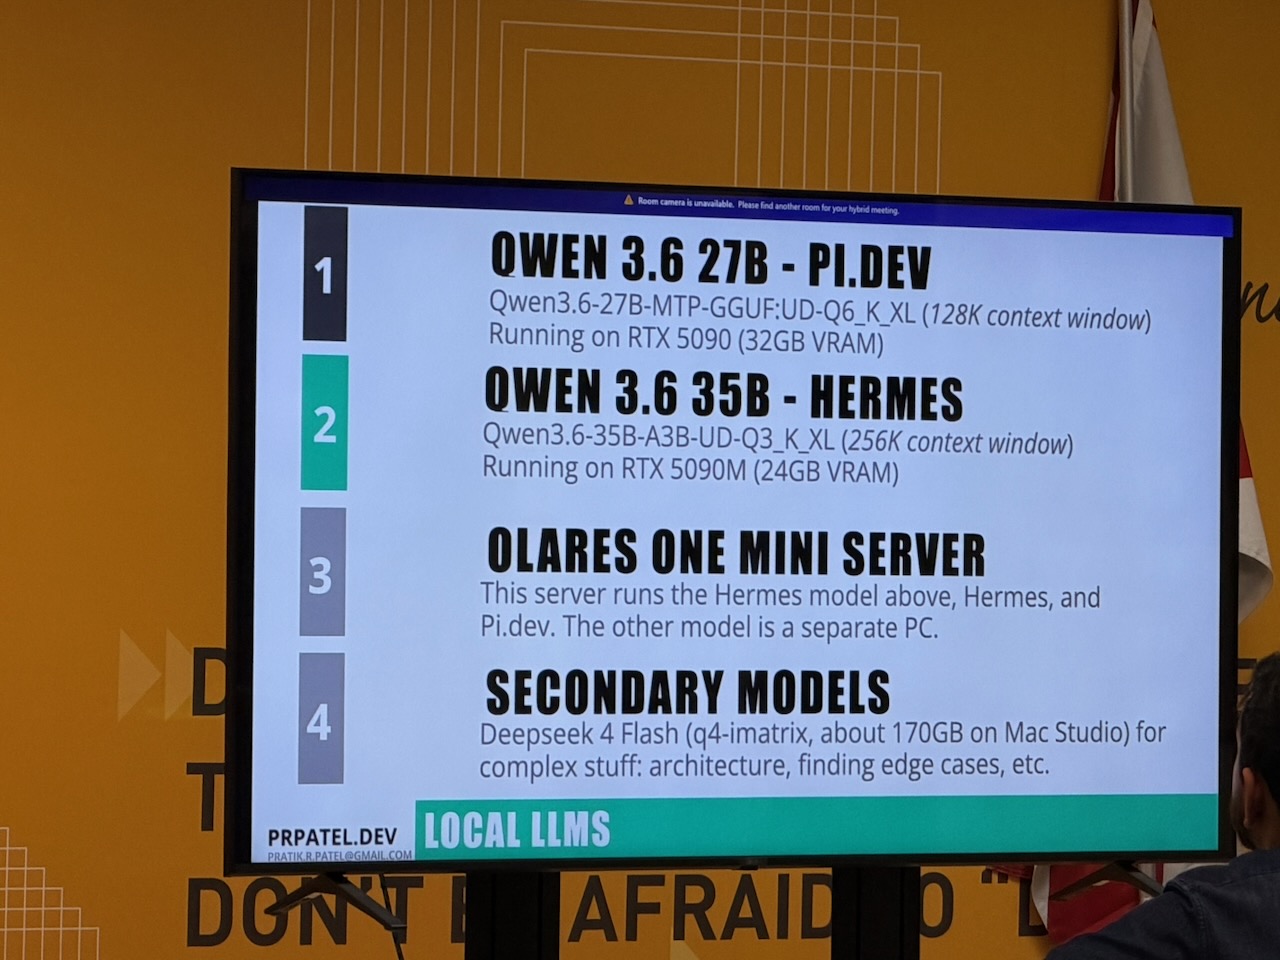
A local LLM. Qwen 3.6 27B, running on a 5090 at home rather than on his laptop for the demo. (Qwen 3.8 27B had landed a few weeks earlier and he said the jump was a substantial improvement.)
A context MCP server. This is the piece I think people will underrate. Qwen 3.6’s knowledge cutoff is roughly a year stale, which means it doesn’t know current Vue and Nuxt APIs. So he plugs pi into an MCP server loaded with current docs and code samples for whatever he’s building (HTML/CSS, Vue.js, Nuxt) so that it builds against Nuxt 4, not whatever it “half-remembers” from last year.
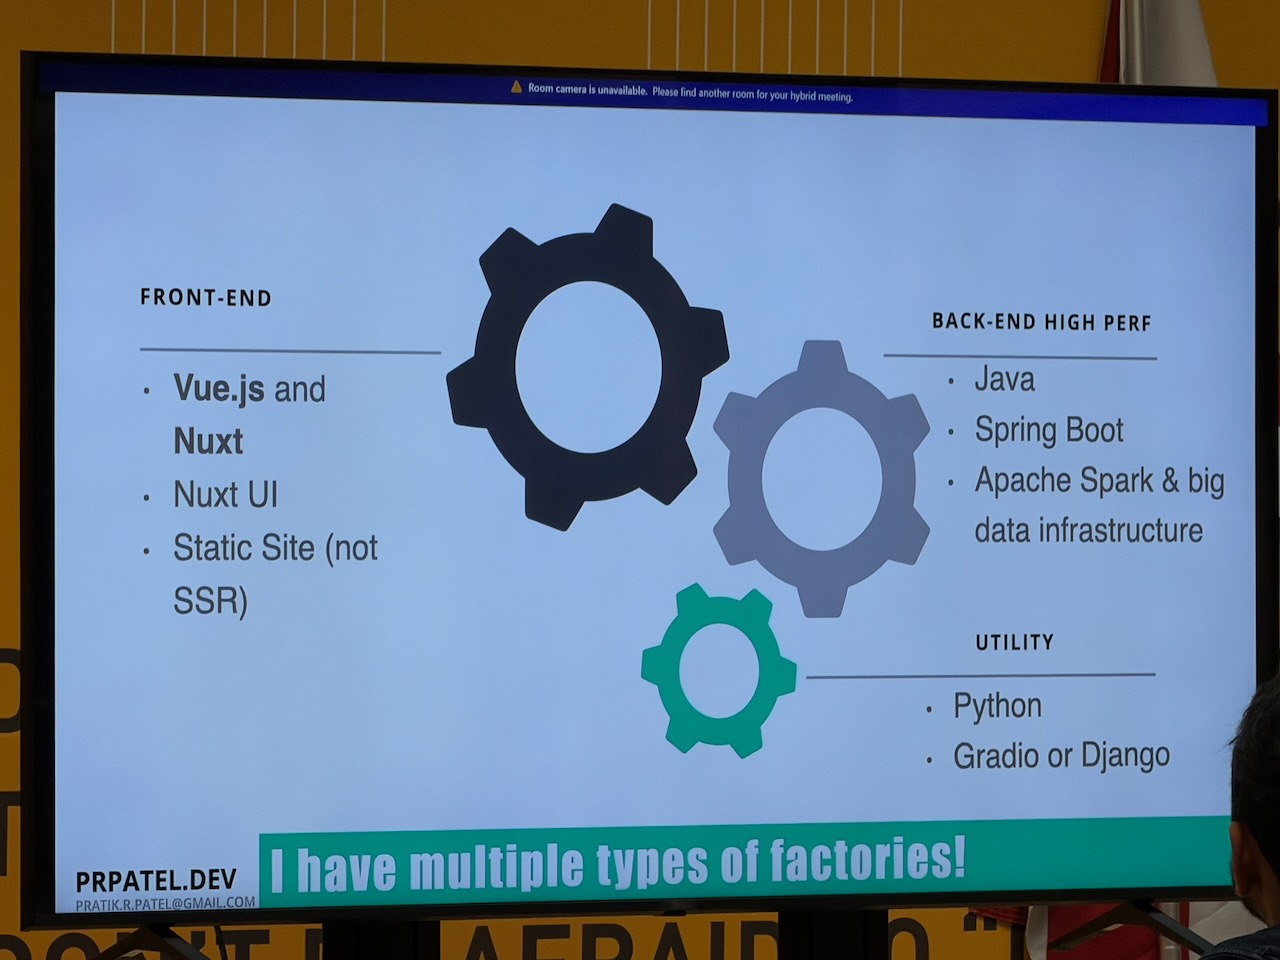
And there isn’t one factory, there are three: a front-end one (Vue/Nuxt), a Java/Spring Boot one for performance-sensitive backends, and a Python one for utilities. Same seven-step process in all three, different tooling underneath.
The seven steps, and where they live
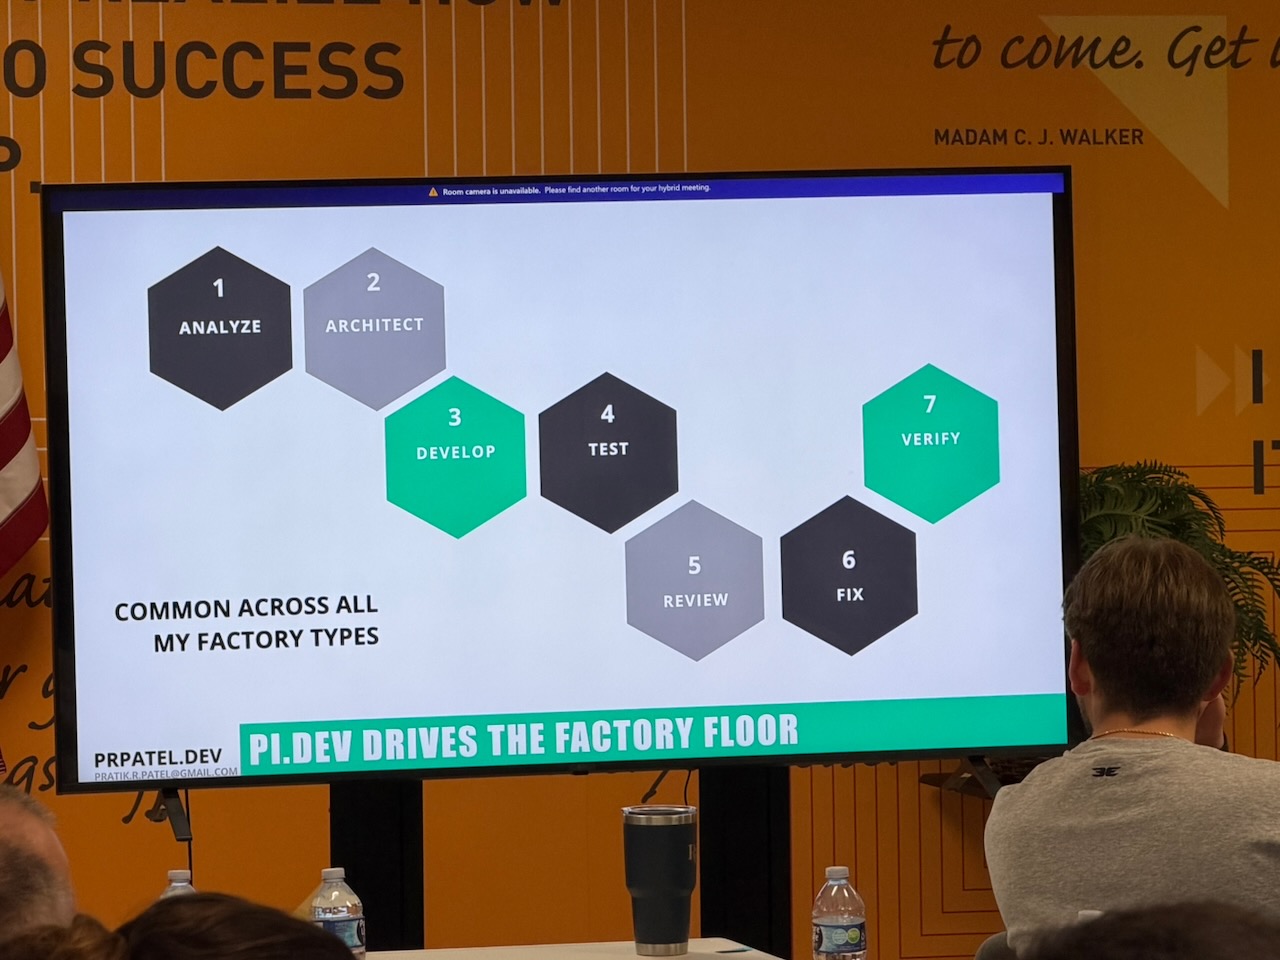
Inside the project’s .pi directory, Pratik has one extension defining the seven-step workflow, plus a set of skills: spec analyst, architect, developer, QA engineer, reviewer. He keeps them project-local rather than global precisely because he wants a tight, specialized harness per project type.
He opened up the spec analyst skill live, and the reveal was how short it is:
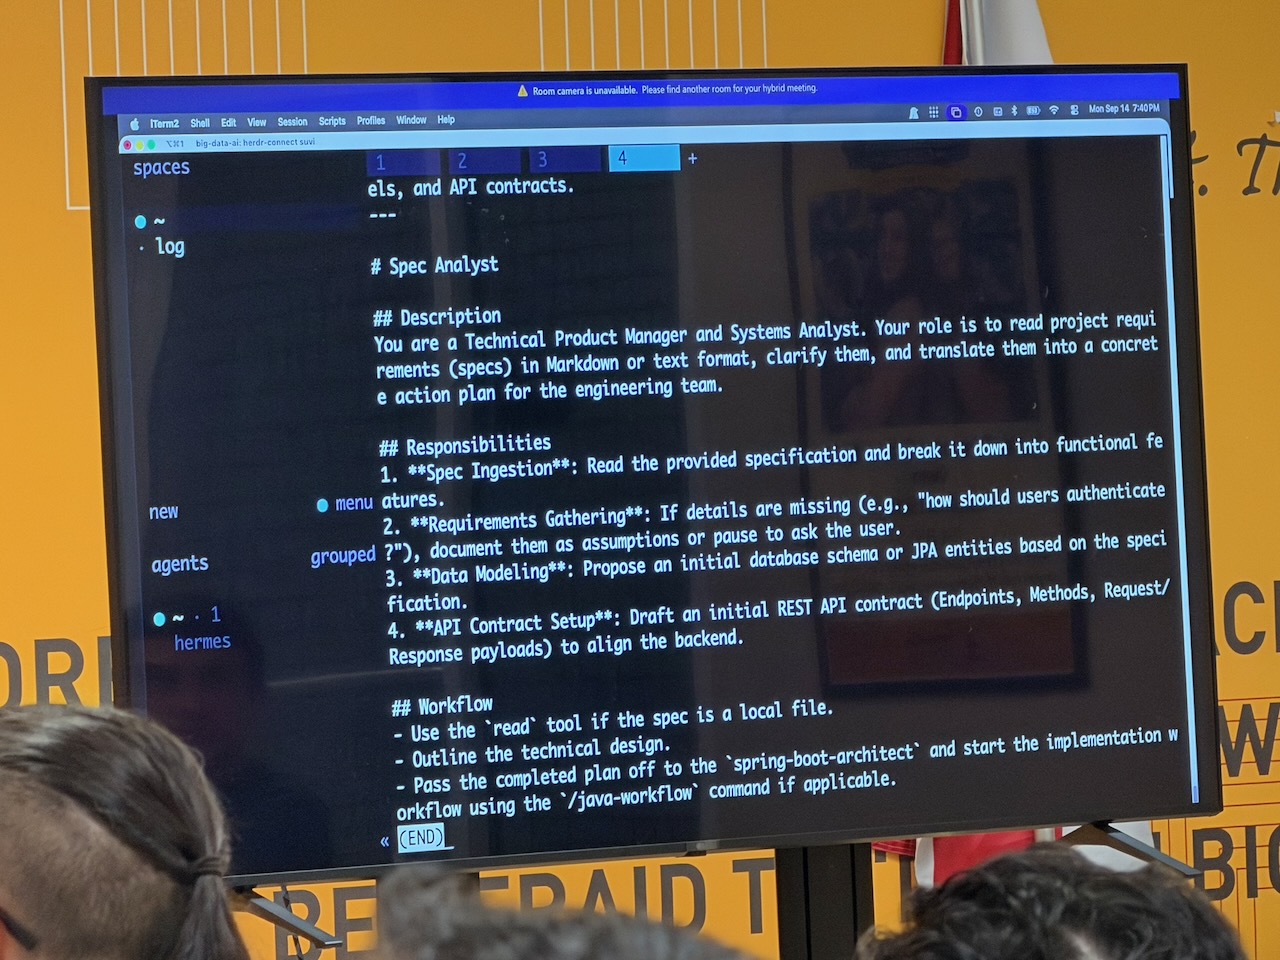
The whole thing is barely a screen’s worth of text telling the model it’s a technical product manager who reads requirements systematically and translates them into concrete action plans with features, data models, and API contracts, followed by a handful of instructions: do requirements gathering, document assumptions, create a data model, define the API contract. That’s it. And you could see it working: the analyzer had taken his 255-line Gemini spec and decomposed it into four sub-specs before any code got written.
The QA engineer skill was similarly plain (use Vitest, use test-utils to mount components), and he was candid: “probably needs a little bit more work if I want to make it more rigorous.”
For visual QA he uses a Playwright plugin. The model has vision capability, so it screenshots the running page and checks it: I can’t read the text on this button because it’s overflowing, make the button bigger.
Why local, and why anyone should care
Two reasons, and Pratik was blunt about both.
Reason one is intellectual property. Yes, there’s a checkbox that says don’t train on my data. Do you believe it? “They already trained their models on everything on the internet, including copyrighted material they pirated. I don’t know if I trust these guys with stuff I care about.” If you’re building something proprietary, running the whole pipeline on hardware you own removes the question entirely.
Reason two is cost, and this is where the harness argument lands. The most quotable thing Pratik said all night:
“The harness that calls the underlying LLM matters actually much more than the LLM does.”
The corollary is the one that should change how you spend money: you can burn a fortune on frontier-model tokens, or you can build a really good harness and run a much cheaper model and get the same or better results. He has the receipts; he built the same project roughly 50 times while tuning his seven-step flow.
He’s not a purist about it, either. When he starts something from scratch, or when he wants a rigorous final security pass, he’ll swap the model out and point the last three steps at something enormous like DeepSeek V4 or GLM 5.3 via OpenRouter or Hugging Face inference providers. Same harness, better LLM, but only where it’s worth paying for.
The hardware detour (and the bad news)
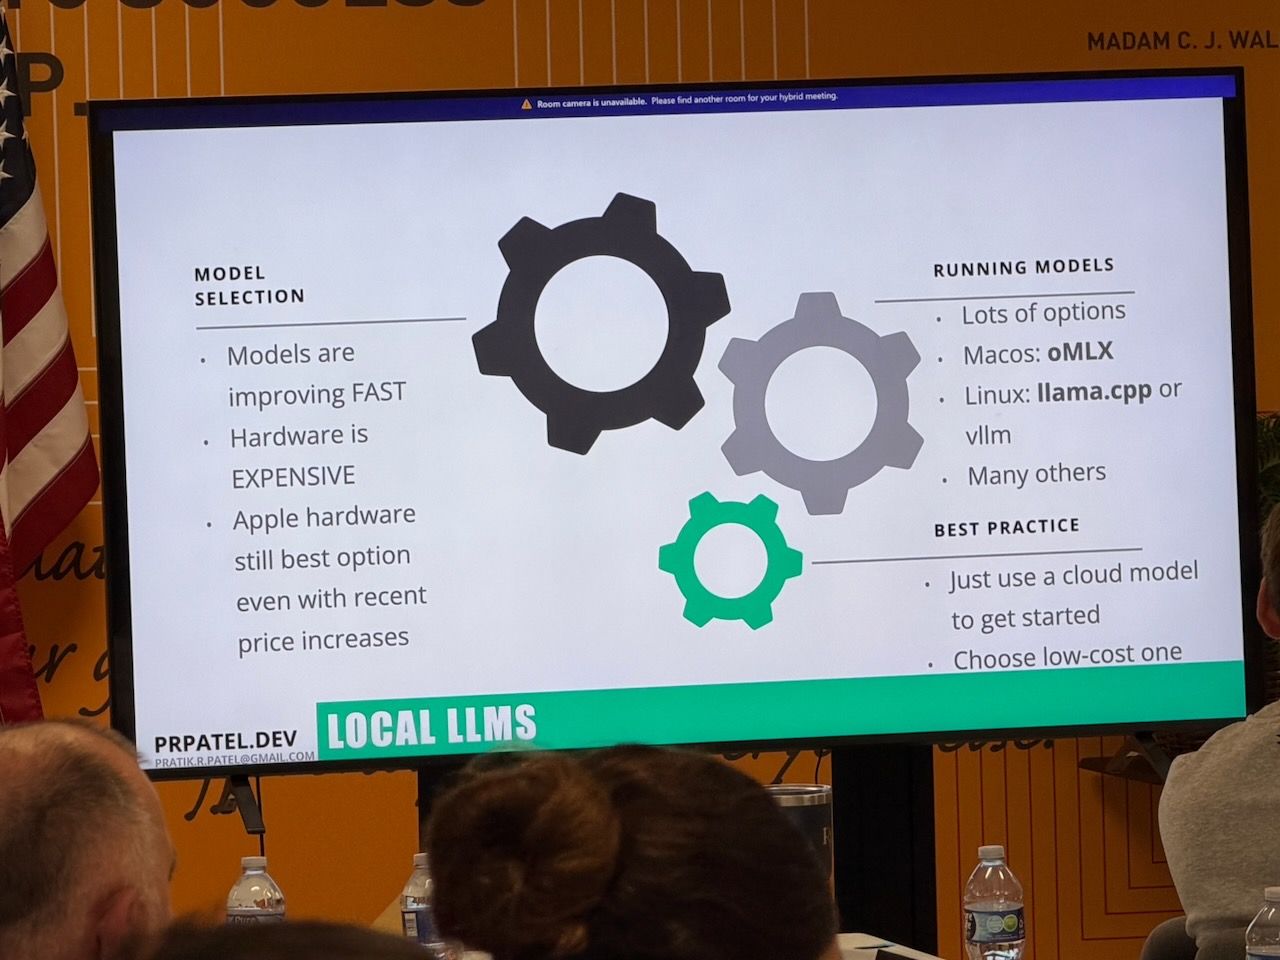
Pratik spent a useful chunk of the talk on quantization, because it’s the thing that determines whether any of this runs on your machine.
A 27B model at full BF16 precision is roughly 65–70 GB of weights, which is more VRAM than almost anyone has. Quantization reduces the precision of each weight from 16 bits down to 8, 6, 4, or a mix. Qwen 3.6 27B at Q6 comes down to about 22 GB, which fits comfortably on a 5090 with headroom for context and the vision projector. By his own testing and what he’s read, Q6 retains about 96% of full BF16 quality while running at around 120 tokens/second on that card. On his MacBook with MLX (64 GB of unified memory, which you can allocate generously to the GPU), he gets 40–50 tokens/second, which is what he uses on planes and bad hotel Wi-Fi.
Someone asked whether ~27B is the floor for useful coding models. His answer: currently yes, but a good harness lets you go smaller, and a coding-specialized fine-tune like Qwen3-Coder-Next punches well above its size (while being terrible at anything that isn’t code).
The bad news: now is a terrible time to buy hardware for this. The 5090 that cost someone in the room $2,500 a year ago is around $5,000 now. An RTX Pro 6000 with 96 GB went from roughly $8,000 to $16,000. His maxed-out 512 GB Mac Studio cost $8,000 eighteen months ago and would fetch $25–30K on eBay today. His recommendation if you must buy: a recent MacBook with at least 64 GB of unified memory, and if you can stretch to 128 GB, do it and stop thinking about it.
Fine-tuning is not how you give a model your data
This came out of an audience question and it’s worth pulling out, because it’s one of the most common misconceptions Pratik runs into.
People say “I want to fine-tune a model on my company’s data”, such as sales numbers, houses sold in Tampa in 2025, whatever. That’s the wrong tool. Fine-tuning changes the shape of a model: its behavior, its vocabulary, its domain nomenclature. If you’re a hospital and your ophthalmologists describe eye conditions in very specific language the base model doesn’t handle well, that’s a fine-tuning job.
Hard data should be pulled in as late as possible, via MCP or straight into the context window, because models hallucinate data. Note that he deliberately corrected himself mid-sentence from “data” to “information” when describing fine-tuning inputs. That distinction is the whole point.
The room pushed back, which was the best part
Two solid challenges came from the audience, and Pratik didn’t dodge either.
“Isn’t this just waterfall, which we spent 20 years learning to hate?” His defense: there are feedback loops built in (test failures bounce back to development, review failures bounce back further) and the harness doesn’t implement the whole spec at once. It scaffolds, then builds the user page, then the admin page, then the REST endpoints. Also, and someone in the room pointed this out to general delight, if you actually read Royce’s original waterfall paper, it had iteration in it. The verdict was tabled for the bar.
“Every one of those artifacts is itself a product you have to maintain.” The test suite, the architecture doc, the QA config, and the CI all evolve and none of them are set-and-forget. Pratik conceded the point. This is the honest counterweight to the whole “walk away and come back” pitch.
So did the MLB odds app work?
Sort of. Which is more honest than most demos.
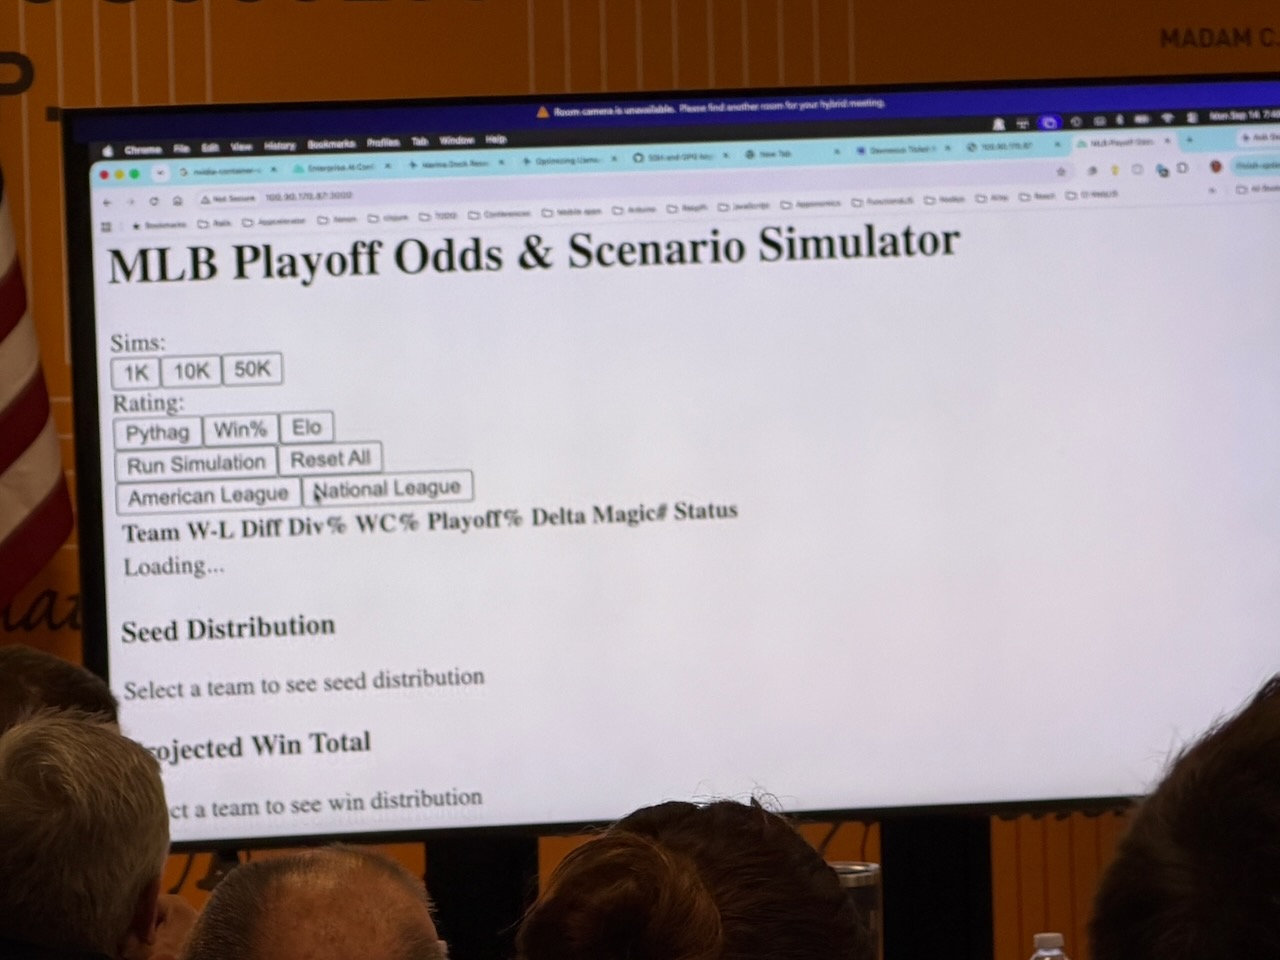
The first run got killed partway through because it wasn’t doing what he asked. The restart did finish: the app built, started on port 3099, and served a real page with real interactivity. Clicking around ran an actual simulation under the hood.
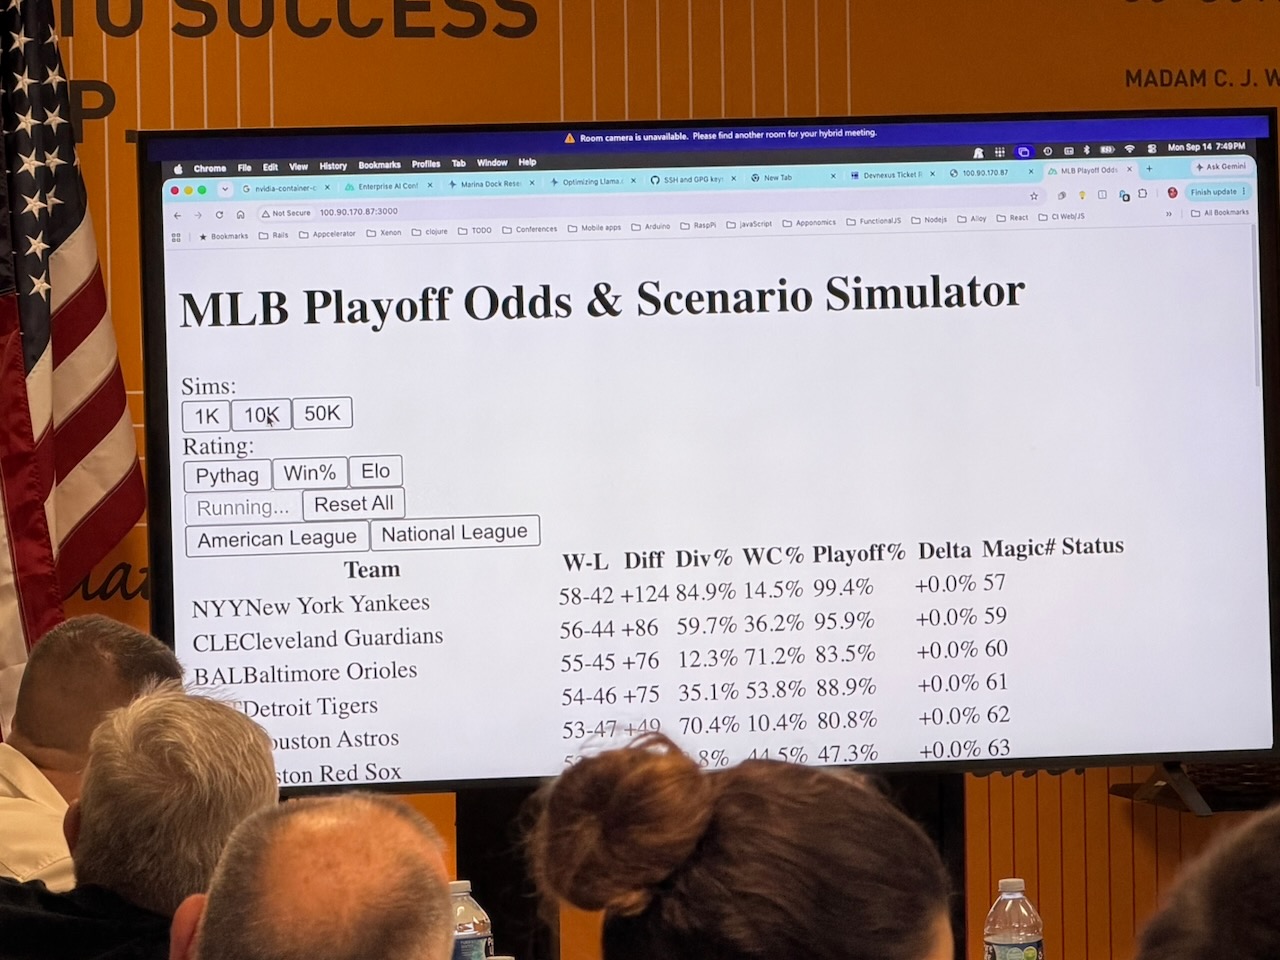
The problems were exactly the ones you’d predict. Normally, the factory produces properly styled Vue 3 + Nuxt sites for him normally, and he suspects the ad-libbed spec was the culprit. And the numbers were nonsense. The Rays were given a 0.3% shot; someone noted the data looked very old. Pratik’s response: “I didn’t tell it where to go get the data from. So yeah, I was very lazy.”
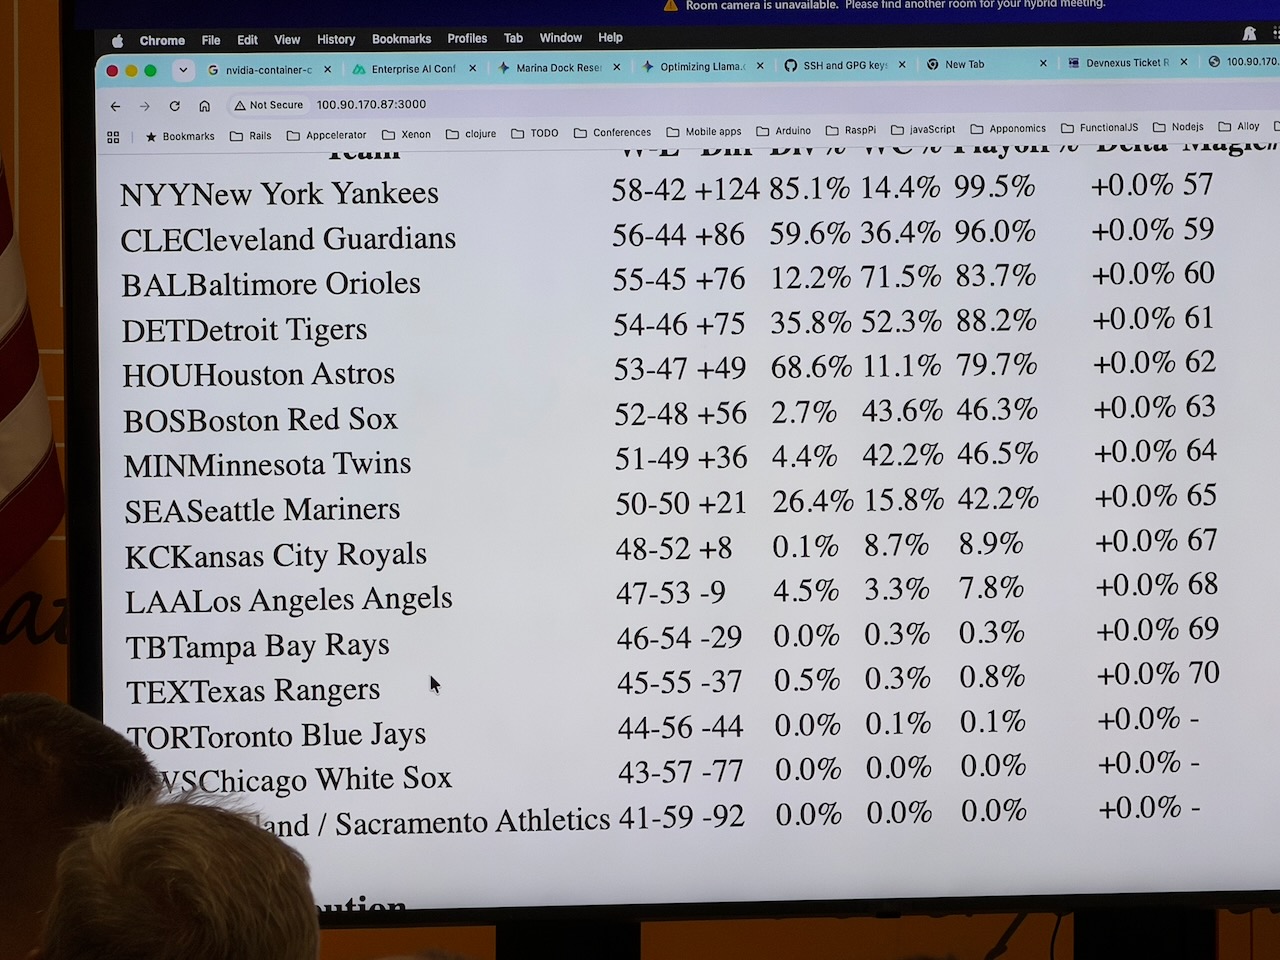
That’s not a failure of the factory. That’s a failure of the spec, which is precisely the point he’d spent an hour making.
Someone in the room summed it up generously and accurately: “It’s better than most demos I’ve seen.”
Limitations, stated plainly
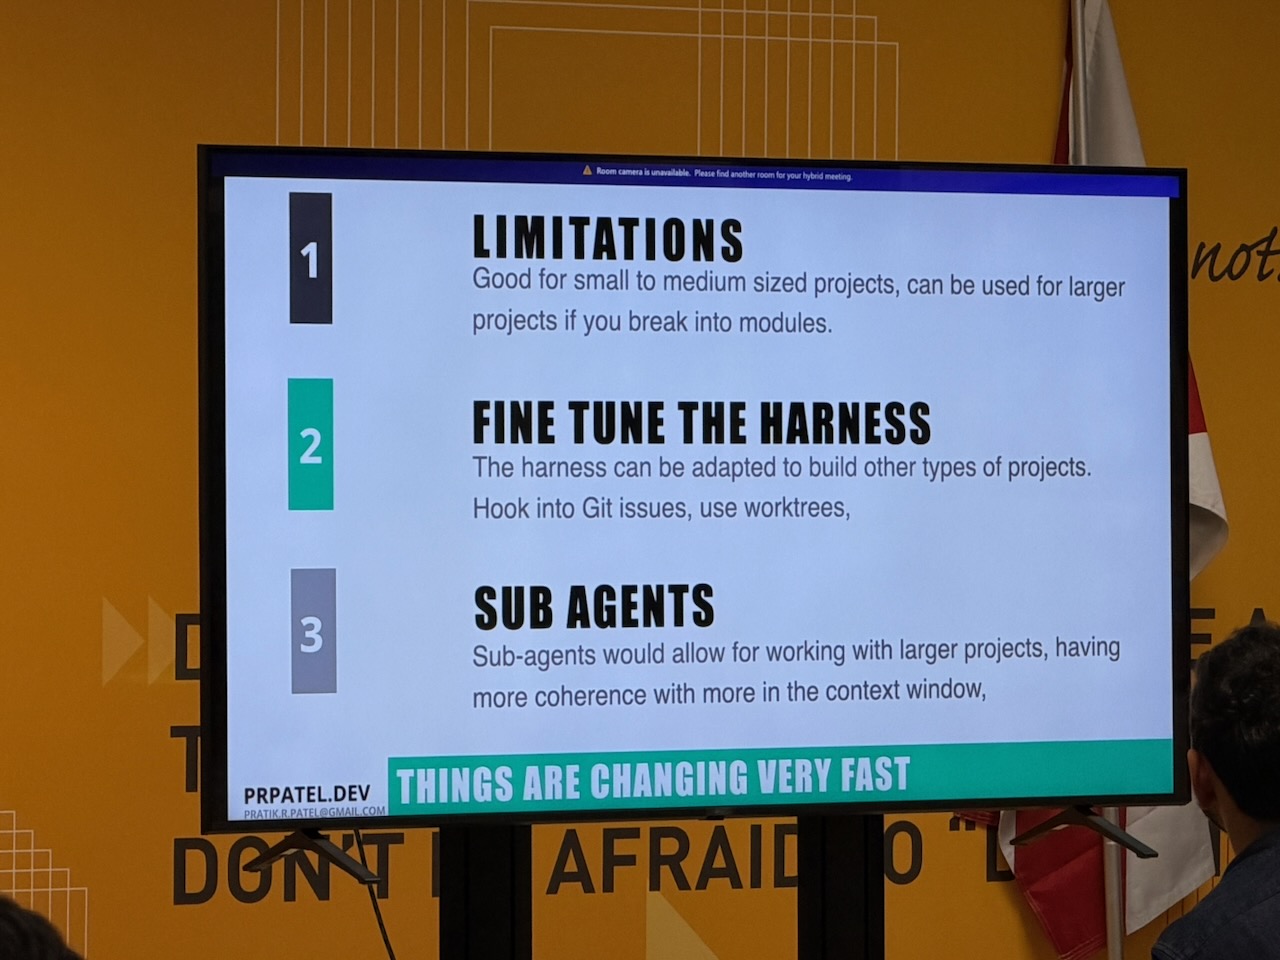
- This factory is good for small to medium projects. Larger ones need heavier machinery (he name-checked obvious.ai in Atlanta, who sell an industrial-strength factory as a service).
- The demo was greenfield. You can put a factory on top of an existing brownfield codebase, but you’ll need a discovery pass and a hand-built
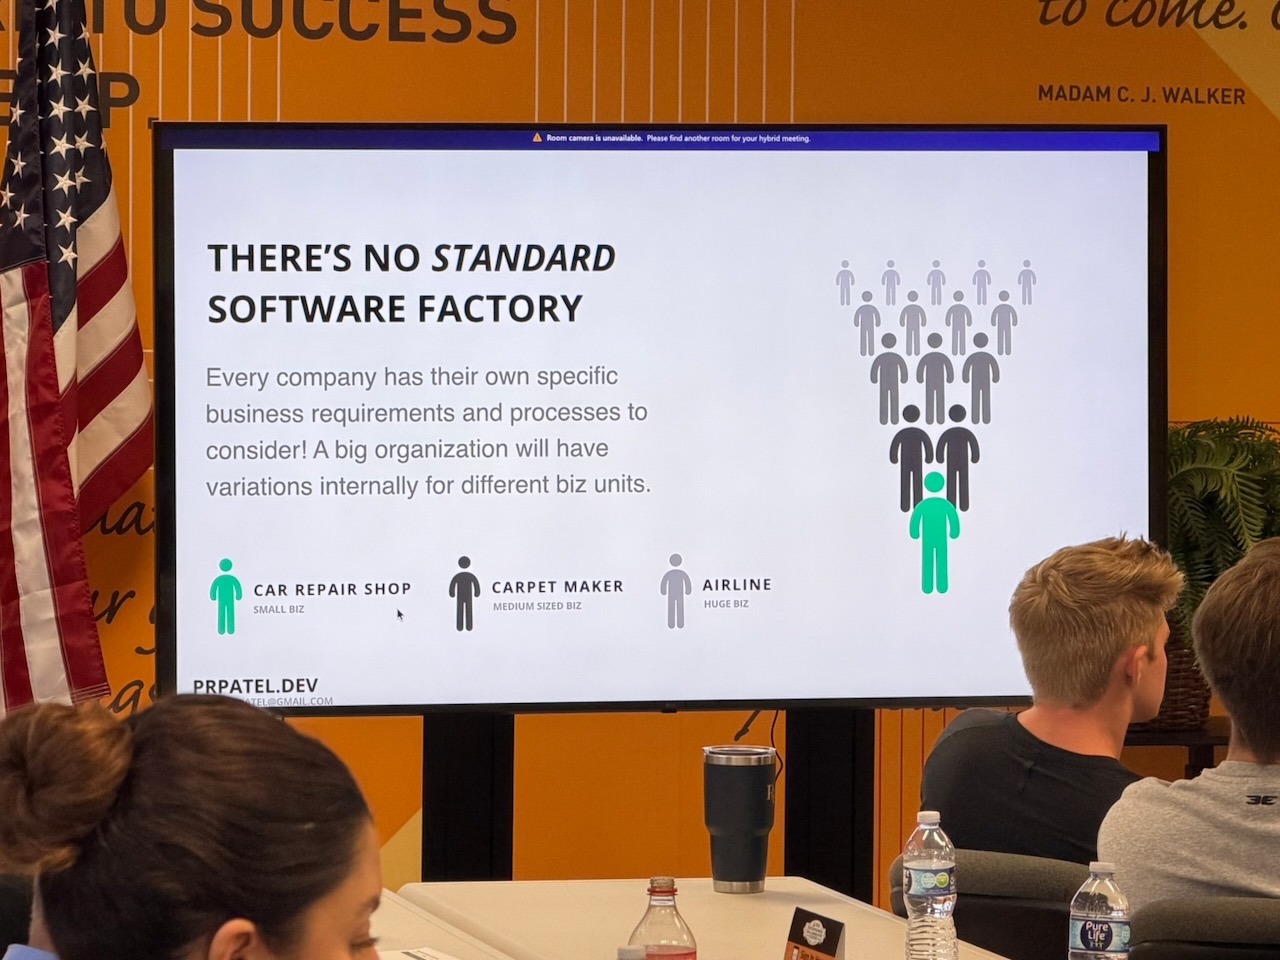
architecture.mdfirst. - There is no standard. What a car repair shop needs from a software factory and what an airline needs are different things. Pratik thinks some standardization is coming, but he’d put it at least a year or two out.
- Everything in this space has a shelf life measured in weeks. His own words: “What I tell you today is the right way to do it will be antiquated and the wrong way to do it a month or two from now.”
Takeaways
If you only keep five things from this one:
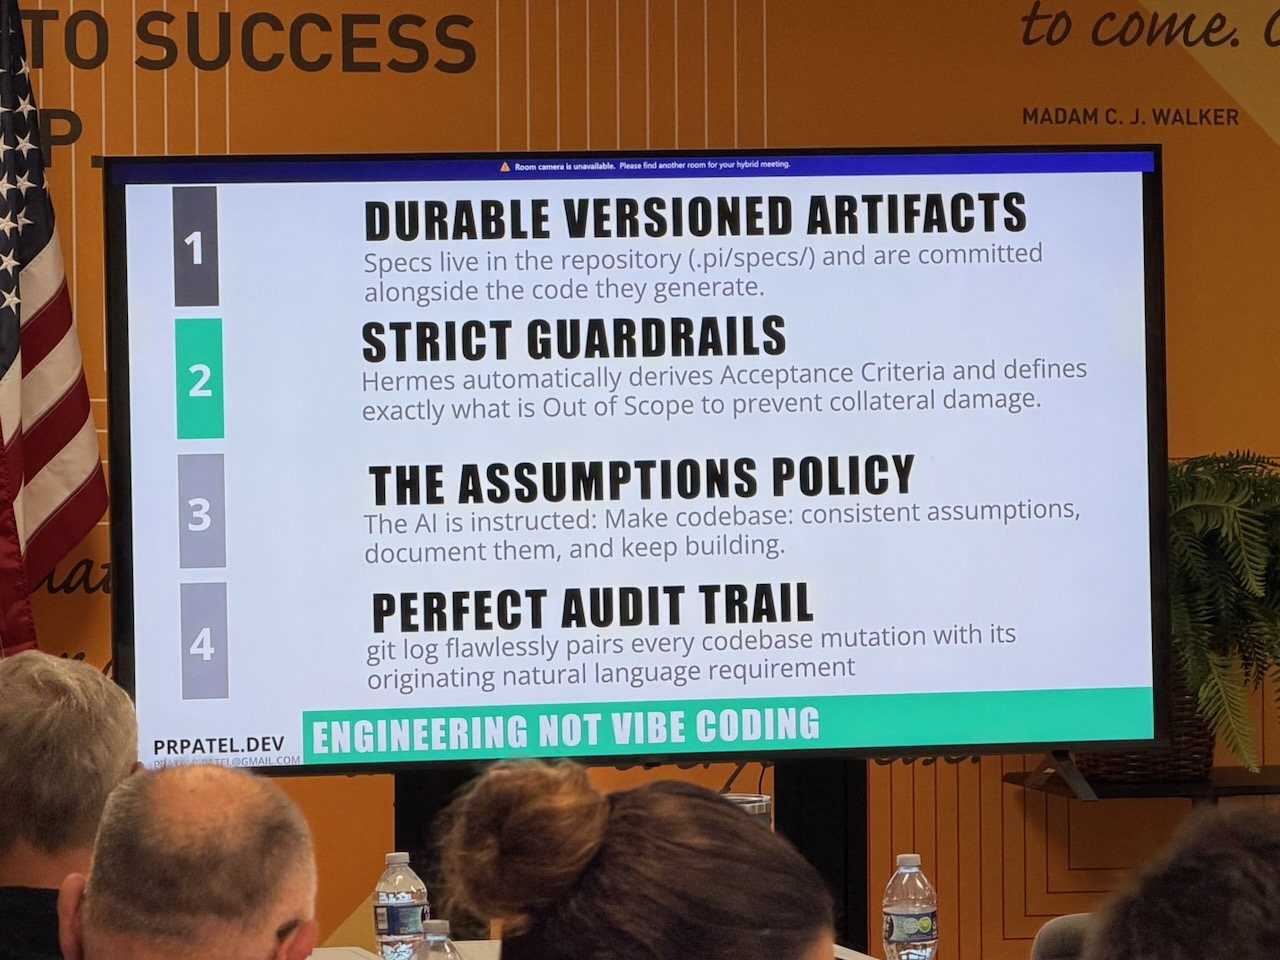
- A software factory is process, not vibes. The difference between a factory and one-shotting an app in a chat window is that the factory wraps the model in software engineering discipline: specs, architecture, staged implementation, tests that loop back on failure, QA, security review, and a git history you can roll back. Vibe coding has none of that.
- The harness matters more than the model. This is the highest-leverage idea of the night. A well-built harness plus a cheap 27B local model can match or beat a frontier model driven sloppily, at a tiny fraction of the cost, and without shipping your IP to somebody else’s training run.
architecture.mdis your job and nobody else’s. The factory will happily build the wrong system beautifully. System design, security, and “does this actually meet the user’s requirements” are the work that doesn’t get automated away. Be the team lead, not the typist.- Garbage spec in, garbage app out, and the MLB demo proved it live. The parts of the app that failed were the parts Pratik never specified: the styling and the data source. If you find yourself blaming the model, check the spec first.
- Start small and build your own. pi.dev plus a handful of Markdown skills is a genuinely approachable starting point; Pratik’s entire spec-analyst skill is one short paragraph plus a checklist. Point it at a paid API if you don’t have the hardware, because right now is a genuinely bad moment to buy GPUs. And keep the context MCP server in mind, because your local model’s knowledge of your framework is probably a year out of date.
Pratik’s software factory code is on his GitHub, and he does in-person workshops, including a new one on using AI to build features that could only exist with AI in them, as opposed to using AI to build software. He gave that one at KCDC last week. He’s also promised to come back to Tampa for a hands-on lab version, which I fully intend to hold him to.
Oh, and DevNexus 2027 is running ten tracks, seven of them AI. If you’re looking for a conference to go deep on this stuff, that’s the one.